shishirpatil--gorilla
 wehub-resource-sync
351 行
17 KiB
Markdown
351 行
17 KiB
Markdown
# Berkeley Function Calling Leaderboard (BFCL)
|
|
|
|
## Table of Contents
|
|
|
|
- [Berkeley Function Calling Leaderboard (BFCL)](#berkeley-function-calling-leaderboard-bfcl)
|
|
- [Table of Contents](#table-of-contents)
|
|
- [Introduction](#introduction)
|
|
- [Installation \& Setup](#installation--setup)
|
|
- [Basic Installation](#basic-installation)
|
|
- [Installing from PyPI](#installing-from-pypi)
|
|
- [Extra Dependencies for Self-Hosted Models](#extra-dependencies-for-self-hosted-models)
|
|
- [Configuring Project Root Directory](#configuring-project-root-directory)
|
|
- [Setting up Environment Variables](#setting-up-environment-variables)
|
|
- [Configuring SerpAPI for Web Search Category](#configuring-serpapi-for-web-search-category)
|
|
- [Running Evaluations](#running-evaluations)
|
|
- [Generating LLM Responses](#generating-llm-responses)
|
|
- [Selecting Models and Test Categories](#selecting-models-and-test-categories)
|
|
- [Selecting Specific Test Cases with `--run-ids`](#selecting-specific-test-cases-with---run-ids)
|
|
- [Output and Logging](#output-and-logging)
|
|
- [For API-based Models](#for-api-based-models)
|
|
- [For Locally-hosted OSS Models](#for-locally-hosted-oss-models)
|
|
- [For Pre-existing OpenAI-compatible Endpoints](#for-pre-existing-openai-compatible-endpoints)
|
|
- [(Alternate) Script Execution for Generation](#alternate-script-execution-for-generation)
|
|
- [Evaluating Generated Responses](#evaluating-generated-responses)
|
|
- [Output Structure](#output-structure)
|
|
- [(Optional) WandB Evaluation Logging](#optional-wandb-evaluation-logging)
|
|
- [(Alternate) Script Execution for Evaluation](#alternate-script-execution-for-evaluation)
|
|
- [Contributing \& How to Add New Models](#contributing--how-to-add-new-models)
|
|
- [Additional Resources](#additional-resources)
|
|
|
|
---
|
|
|
|
## Introduction
|
|
|
|
We introduce the Berkeley Function Calling Leaderboard (BFCL), the **first comprehensive and executable function call evaluation** dedicated to assessing Large Language Models' (LLMs) ability to invoke functions. Unlike previous evaluations, BFCL accounts for various forms of function calls, diverse scenarios, and executability.
|
|
|
|
💡 Read more in our blog posts:
|
|
|
|
- [BFCL v1: Simple, Parallel, and Multiple Function Call eval with AST](https://gorilla.cs.berkeley.edu/blogs/8_berkeley_function_calling_leaderboard.html)
|
|
- [BFCL v2: Enterprise and OSS-contributed Live Data](https://gorilla.cs.berkeley.edu/blogs/12_bfcl_v2_live.html)
|
|
- [BFCL v3: Multi-Turn & Multi-Step Function Call Evaluation](https://gorilla.cs.berkeley.edu/blogs/13_bfcl_v3_multi_turn.html)
|
|
- [BFCL V4 Part 1: Agentic Web Search](https://gorilla.cs.berkeley.edu/blogs/15_bfcl_v4_web_search.html)
|
|
- [BFCL V4 Part 2: Agentic Memory Management](https://gorilla.cs.berkeley.edu/blogs/16_bfcl_v4_memory.html)
|
|
- [BFCL V4 Part 3: Agentic Format Sensitivity](https://gorilla.cs.berkeley.edu/blogs/17_bfcl_v4_prompt_variation.html)
|
|
|
|
🦍 See the live leaderboard at [Berkeley Function Calling Leaderboard](https://gorilla.cs.berkeley.edu/leaderboard.html#leaderboard)
|
|
|
|
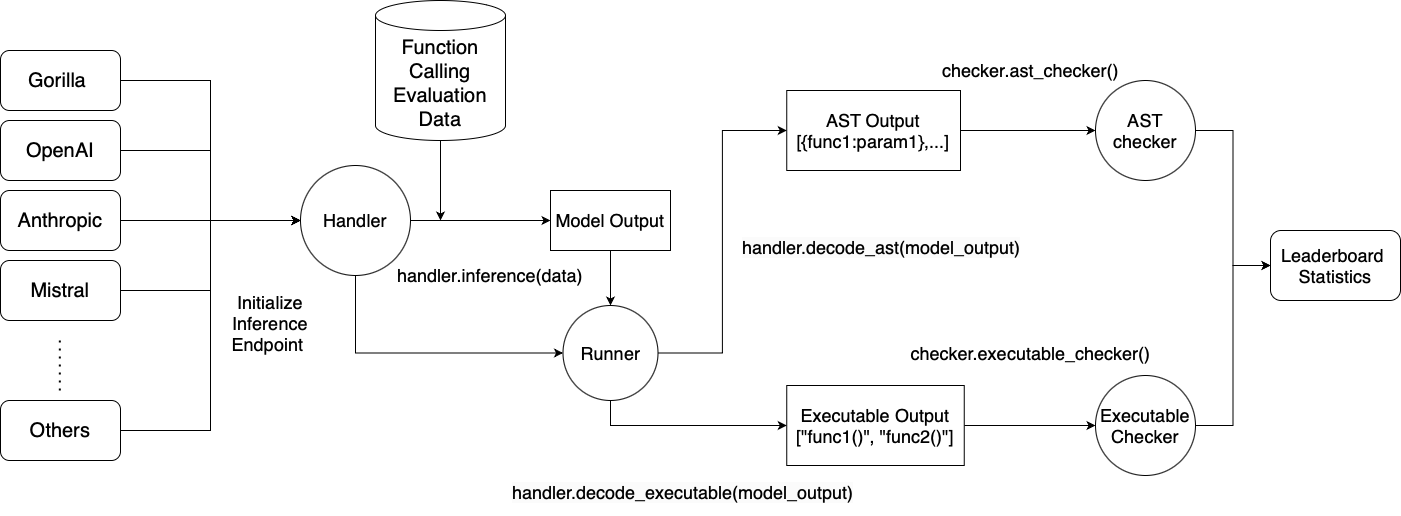
|
|
|
|
---
|
|
|
|
## Installation & Setup
|
|
|
|
### Basic Installation
|
|
|
|
```bash
|
|
# Create a new Conda environment with Python 3.10
|
|
conda create -n BFCL python=3.10
|
|
conda activate BFCL
|
|
|
|
# Clone the Gorilla repository
|
|
git clone https://github.com/ShishirPatil/gorilla.git
|
|
|
|
# Change directory to the `berkeley-function-call-leaderboard`
|
|
cd gorilla/berkeley-function-call-leaderboard
|
|
|
|
# Install the package in editable mode
|
|
pip install -e .
|
|
```
|
|
|
|
### Installing from PyPI
|
|
|
|
If you simply want to run the evaluation without making code changes, you can
|
|
install the prebuilt wheel instead. **Be careful not to confuse our package with
|
|
the *unrelated* `bfcl` project on PyPI—make sure you install `bfcl-eval`:**
|
|
|
|
```bash
|
|
pip install bfcl-eval # Be careful not to confuse with the unrelated `bfcl` project on PyPI!
|
|
```
|
|
|
|
### Extra Dependencies for Self-Hosted Models
|
|
|
|
For locally hosted models, choose one of the following backends, ensuring you have the right GPU and OS setup:
|
|
|
|
`sglang` is *much faster* than `vllm` in our specific multi-turn use case, but it only supports newer GPUs with SM 80+ (Ampere etc).
|
|
If you are using an older GPU (T4/V100), you should use `vllm` instead as it supports a much wider range of GPUs.
|
|
|
|
**Using `vllm`:**
|
|
```bash
|
|
pip install -e .[oss_eval_vllm]
|
|
```
|
|
|
|
**Using `sglang`:**
|
|
```bash
|
|
pip install -e .[oss_eval_sglang]
|
|
```
|
|
|
|
*Optional:* If using `sglang`, we recommend installing `flashinfer` for speedups. Find instructions [here](https://docs.flashinfer.ai/installation.html).
|
|
|
|
### Configuring Project Root Directory
|
|
|
|
**Important:** If you installed the package from PyPI (using `pip install bfcl-eval`), you **must** set the `BFCL_PROJECT_ROOT` environment variable to specify where the evaluation results and score files should be stored.
|
|
Otherwise, you'll need to navigate deep into the Python package's source code folder to access the evaluation results and configuration files.
|
|
|
|
For editable installations (using `pip install -e .`), setting `BFCL_PROJECT_ROOT` is *optional*--it defaults to the `berkeley-function-call-leaderboard` directory.
|
|
|
|
Set `BFCL_PROJECT_ROOT` as an environment variable in your shell environment:
|
|
|
|
```bash
|
|
# In your shell environment
|
|
export BFCL_PROJECT_ROOT=/path/to/your/desired/project/directory
|
|
```
|
|
|
|
When `BFCL_PROJECT_ROOT` is set:
|
|
|
|
- The `result/` folder (containing model responses) will be created at `$BFCL_PROJECT_ROOT/result/`
|
|
- The `score/` folder (containing evaluation results) will be created at `$BFCL_PROJECT_ROOT/score/`
|
|
- The library will look for the `.env` configuration file at `$BFCL_PROJECT_ROOT/.env` (see [Setting up Environment Variables](#setting-up-environment-variables))
|
|
|
|
### Setting up Environment Variables
|
|
|
|
We store API keys and other configuration variables (separate from the `BFCL_PROJECT_ROOT` variable mentioned above) in a `.env` file. A sample `.env.example` file is distributed with the package.
|
|
|
|
**For editable installations:**
|
|
|
|
```bash
|
|
cp bfcl_eval/.env.example .env
|
|
# Fill in necessary values in `.env`
|
|
```
|
|
|
|
**For PyPI installations (using `pip install bfcl-eval`):**
|
|
|
|
```bash
|
|
cp $(python -c "import bfcl_eval; print(bfcl_eval.__path__[0])")/.env.example $BFCL_PROJECT_ROOT/.env
|
|
# Fill in necessary values in `.env`
|
|
```
|
|
|
|
If you are running any proprietary models, make sure the model API keys are included in your `.env` file. Models like GPT, Claude, Mistral, Gemini, Nova, will require them.
|
|
|
|
The library looks for the `.env` file in the project root, i.e. `$BFCL_PROJECT_ROOT/.env`.
|
|
|
|
#### Configuring SerpAPI for Web Search Category
|
|
|
|
For the `web_search` test category, we use the [SerpAPI](https://serpapi.com/) service to perform web search. You need to sign up for an API key and add it to your `.env` file. You can also switch to other web search APIs by changing the `search_engine_query` function in `bfcl_eval/eval_checker/multi_turn_eval/func_source_code/web_search.py`.
|
|
|
|
---
|
|
|
|
## Running Evaluations
|
|
|
|
### Generating LLM Responses
|
|
|
|
#### Selecting Models and Test Categories
|
|
|
|
- `MODEL_NAME`: For available models, please refer to [SUPPORTED_MODELS.md](./SUPPORTED_MODELS.md). If not specified, the default model `gorilla-openfunctions-v2` is used.
|
|
- `TEST_CATEGORY`: For available test categories, please refer to [TEST_CATEGORIES.md](./TEST_CATEGORIES.md). If not specified, all categories are included by default.
|
|
|
|
You can provide multiple models or test categories by separating them with commas. For example:
|
|
|
|
```bash
|
|
bfcl generate --model claude-3-5-sonnet-20241022-FC,gpt-4o-2024-11-20-FC --test-category simple_python,parallel,live_multiple,multi_turn
|
|
```
|
|
|
|
#### Selecting Specific Test Cases with `--run-ids`
|
|
|
|
Sometimes you may only need to regenerate a handful of test entries—for instance when iterating on a new model or after fixing an inference bug. Passing the `--run-ids` flag lets you target **exact test IDs** rather than an entire category:
|
|
|
|
```bash
|
|
bfcl generate --model MODEL_NAME --run-ids # --test-category will be ignored
|
|
```
|
|
|
|
When this flag is set the generation pipeline reads a JSON file named
|
|
`test_case_ids_to_generate.json` located in the *project root* (the same
|
|
place where `.env` lives). The file should map each test category to a list of
|
|
IDs to run:
|
|
|
|
```json
|
|
{
|
|
"simple_python": ["simple_python_102", "simple_python_103"],
|
|
"multi_turn_base": ["multi_turn_base_15"]
|
|
}
|
|
```
|
|
|
|
> Note: When using `--run-ids`, the `--test-category` flag is ignored.
|
|
|
|
A sample file is provided at `bfcl_eval/test_case_ids_to_generate.json.example`; **copy it to your project root** so the CLI can pick it up regardless of your working directory:
|
|
|
|
**For editable installations:**
|
|
|
|
```bash
|
|
cp bfcl_eval/test_case_ids_to_generate.json.example ./test_case_ids_to_generate.json
|
|
```
|
|
|
|
**For PyPI installations:**
|
|
|
|
```bash
|
|
cp $(python -c "import bfcl_eval, pathlib; print(pathlib.Path(bfcl_eval.__path__[0]) / 'test_case_ids_to_generate.json.example')") $BFCL_PROJECT_ROOT/test_case_ids_to_generate.json
|
|
```
|
|
|
|
Once `--run-ids` is provided only the IDs listed in the JSON will be evaluated.
|
|
|
|
#### Output and Logging
|
|
|
|
- By default, generated model responses are stored in a `result/` folder under the project root (which defaults to the package directory): `result/MODEL_NAME/BFCL_v3_TEST_CATEGORY_result.json`.
|
|
- You can customise the location by setting the `BFCL_PROJECT_ROOT` environment variable or passing the `--result-dir` option.
|
|
|
|
An inference log is included with the model responses to help analyze/debug the model's performance, and to better understand the model behavior. For more verbose logging, use the `--include-input-log` flag. Refer to [LOG_GUIDE.md](./LOG_GUIDE.md) for details on how to interpret the inference logs.
|
|
|
|
#### For API-based Models
|
|
|
|
```bash
|
|
bfcl generate --model MODEL_NAME --test-category TEST_CATEGORY --num-threads 1
|
|
```
|
|
|
|
- Use `--num-threads` to control the level of parallel inference. The default (`1`) means no parallelization.
|
|
- The maximum allowable threads depends on your API's rate limits.
|
|
|
|
#### For Locally-hosted OSS Models
|
|
|
|
```bash
|
|
bfcl generate \
|
|
--model MODEL_NAME \
|
|
--test-category TEST_CATEGORY \
|
|
--backend {sglang|vllm} \
|
|
--num-gpus 1 \
|
|
--gpu-memory-utilization 0.9 \
|
|
--local-model-path /path/to/base/model \
|
|
--enable-lora \
|
|
--max-lora-rank 128 \
|
|
--lora-modules module1="/path/to/lora/adapter1" module2="/path/to/lora/adapter2" # ← optional
|
|
```
|
|
|
|
- Choose your backend using `--backend sglang` or `--backend vllm`. The default backend is `vllm`.
|
|
- Control GPU usage by adjusting `--num-gpus` (default `1`, relevant for multi-GPU tensor parallelism) and `--gpu-memory-utilization` (default `0.9`), which can help avoid out-of-memory errors.
|
|
- `--local-model-path` (optional): Point this flag at a directory that already contains the model's files (`config.json`, tokenizer, weights, etc.). Use it only when you've pre-downloaded the model and the weights live somewhere other than the default `$HF_HOME` cache.
|
|
- `--enable-lora` (optional): Enable LoRA for the vLLM backend. This flag is required to use LoRA modules. This only works when backend is `vllm`.
|
|
- `--max-lora-rank` (optional): Specify the maximum LoRA rank for the vLLM backend. This is an integer value. This only works when backend is `vllm` and `--enable-lora` flag is set.
|
|
- `--lora-modules` (optional): Specify the path to the LoRA modules for the vLLM backend in `name="path"` format. This allows evaluation of fine-tuned models with LoRA adapters. You can specify multiple LoRA modules by repeating this argument. This only works when backend is `vllm` and `--enable-lora` flag is set.
|
|
|
|
##### For Pre-existing OpenAI-compatible Endpoints
|
|
|
|
If you have a server already running (e.g., vLLM in a SLURM cluster), you can bypass the vLLM/sglang setup phase and directly generate responses by using the `--skip-server-setup` flag:
|
|
|
|
```bash
|
|
bfcl generate --model MODEL_NAME --test-category TEST_CATEGORY --skip-server-setup
|
|
```
|
|
|
|
In addition, you should specify the endpoint and port used by the local server. By default, the endpoint is `localhost` and the port is `1053`. These can be overridden by the `LOCAL_SERVER_ENDPOINT` and `LOCAL_SERVER_PORT` environment variables in the `.env` file:
|
|
|
|
```bash
|
|
LOCAL_SERVER_ENDPOINT=localhost
|
|
LOCAL_SERVER_PORT=1053
|
|
```
|
|
|
|
For remote deployments (e.g., via RunPod, ngrok, or enterprise gateways) that require custom authentication or use non-standard base URLs, you can specify a full base URL and API key:
|
|
|
|
```bash
|
|
REMOTE_OPENAI_BASE_URL=https://your-vllm-server.com/v1
|
|
REMOTE_OPENAI_API_KEY=your-api-key-here
|
|
REMOTE_OPENAI_TOKENIZER_PATH=/path/to/local/tokenizer # Optional: specify local tokenizer for local/remote endpoints
|
|
```
|
|
|
|
#### (Alternate) Script Execution for Generation
|
|
|
|
For those who prefer using script execution instead of the CLI, you can run the following command:
|
|
|
|
```bash
|
|
python -m bfcl_eval.openfunctions_evaluation --model MODEL_NAME --test-category TEST_CATEGORY
|
|
```
|
|
|
|
When specifying multiple models or test categories, separate them with **spaces**, not commas. All other flags mentioned earlier are compatible with the script execution method as well.
|
|
|
|
### Evaluating Generated Responses
|
|
|
|
**Important:** You must have generated the model responses before running the evaluation.
|
|
|
|
Once you have the results, run:
|
|
|
|
```bash
|
|
bfcl evaluate --model MODEL_NAME --test-category TEST_CATEGORY
|
|
```
|
|
|
|
If you **only** generated a subset of benchmark entries (e.g. by using `--run-ids` during the generation step or by manually editing the result files) and you wish to evaluate *just* those entries, add the `--partial-eval` flag:
|
|
|
|
```bash
|
|
bfcl evaluate --model MODEL_NAME --test-category TEST_CATEGORY --partial-eval
|
|
```
|
|
|
|
When `--partial-eval` is set, the evaluator silently skips IDs that are not present in the model result file and computes accuracy on the remaining subset. Please note that the score may differ from a full-set evaluation and therefore might not match the official leaderboard numbers.
|
|
|
|
The `MODEL_NAME` and `TEST_CATEGORY` options are the same as those used in the [Generating LLM Responses](#generating-llm-responses) section. For details, refer to [SUPPORTED_MODELS.md](./SUPPORTED_MODELS.md) and [TEST_CATEGORIES.md](./TEST_CATEGORIES.md).
|
|
|
|
If in the previous step you stored the model responses in a custom directory, specify it using the `--result-dir` flag or set `BFCL_PROJECT_ROOT` so the evaluator can locate the files.
|
|
|
|
> Note: For unevaluated test categories, they will be marked as `N/A` in the evaluation result csv files.
|
|
> For summary columns (e.g., `Overall Acc`, `Non_Live Overall Acc`, `Live Overall Acc`, and `Multi Turn Overall Acc`), the score reported will treat all unevaluated categories as 0 during calculation.
|
|
|
|
#### Output Structure
|
|
|
|
Evaluation scores are stored in a `score/` directory under the project root (defaults to the package directory), mirroring the structure of `result/`: `score/MODEL_NAME/BFCL_v3_TEST_CATEGORY_score.json`.
|
|
|
|
- To use a custom directory for the score file, set the `BFCL_PROJECT_ROOT` environment variable or specify `--score-dir`.
|
|
|
|
Additionally, four CSV files are generated in `./score/`:
|
|
|
|
- `data_overall.csv` – Overall scores for each model. This is used for updating the leaderboard.
|
|
- `data_live.csv` – Detailed breakdown of scores for each Live (single-turn) test category.
|
|
- `data_non_live.csv` – Detailed breakdown of scores for each Non-Live (single-turn) test category.
|
|
- `data_multi_turn.csv` – Detailed breakdown of scores for each Multi-Turn test category.
|
|
|
|
#### (Optional) WandB Evaluation Logging
|
|
|
|
If you'd like to log evaluation results to WandB artifacts:
|
|
|
|
```bash
|
|
pip install -e.[wandb]
|
|
```
|
|
|
|
Mkae sure you also set `WANDB_BFCL_PROJECT=ENTITY:PROJECT` in `.env`.
|
|
|
|
#### (Alternate) Script Execution for Evaluation
|
|
|
|
For those who prefer using script execution instead of the CLI, you can run the following command:
|
|
|
|
```bash
|
|
python -m bfcl_eval.eval_checker.eval_runner --model MODEL_NAME --test-category TEST_CATEGORY
|
|
```
|
|
|
|
When specifying multiple models or test categories, separate them with **spaces**, not commas. All other flags mentioned earlier are compatible with the script execution method as well.
|
|
|
|
## Contributing & How to Add New Models
|
|
|
|
We welcome contributions! To add a new model:
|
|
|
|
1. Review `bfcl_eval/model_handler/base_handler.py` and/or `bfcl_eval/model_handler/local_inference/base_oss_handler.py` (if your model is hosted locally).
|
|
2. Implement a new handler class for your model.
|
|
3. Update `bfcl_eval/constants/model_config.py`.
|
|
4. Submit a Pull Request.
|
|
|
|
For detailed steps, please see the [Contributing Guide](./CONTRIBUTING.md).
|
|
|
|
---
|
|
|
|
## Additional Resources
|
|
|
|
- [Discord](https://discord.gg/grXXvj9Whz) (`#leaderboard` channel)
|
|
- [Project Website](https://gorilla.cs.berkeley.edu/leaderboard.html#leaderboard)
|
|
|
|
All the leaderboard statistics, and data used to train the models are released under Apache 2.0.
|
|
BFCL is an open source effort from UC Berkeley and we welcome contributors.
|
|
For any comments, criticisms, or questions, please feel free to raise an issue or a PR. You can also reach us via [email](mailto:huanzhimao@berkeley.edu).
|