cleanlab--cleanlab
 wehub-resource-sync
df40697578
CI / Core Tests: Python 3.12 on ubuntu-latest (push) Has been cancelled
CI / Core Tests: Python 3.10 on windows-latest (push) Has been cancelled
CI / Core Tests: Python 3.11 on windows-latest (push) Has been cancelled
CI / Core Tests: Python 3.12 on windows-latest (push) Has been cancelled
GitHub Pages / deploy (push) Has been cancelled
CI / Core Tests: Python 3.10 on macos-latest (push) Has been cancelled
CI / Core Tests: Python 3.11 on macos-latest (push) Has been cancelled
CI / Core Tests: Python 3.12 on macos-latest (push) Has been cancelled
CI / Core Tests: Python 3.13 on macos-latest (push) Has been cancelled
CI / Core Tests: Python 3.14 on macos-latest (push) Has been cancelled
CI / Core Tests: Python 3.10 on ubuntu-latest (push) Has been cancelled
CI / Core Tests: Python 3.11 on ubuntu-latest (push) Has been cancelled
CI / Core Tests: Python 3.13 on ubuntu-latest (push) Has been cancelled
CI / Core Tests: Python 3.14 on ubuntu-latest (push) Has been cancelled
CI / Core Tests: Python 3.13 on windows-latest (push) Has been cancelled
CI / Core Tests: Python 3.14 on windows-latest (push) Has been cancelled
CI / ML Framework Tests: Python 3.10 on ubuntu-latest (push) Has been cancelled
CI / ML Framework Tests: Python 3.11 on ubuntu-latest (push) Has been cancelled
CI / ML Framework Tests: Python 3.12 on ubuntu-latest (push) Has been cancelled
CI / ML Framework Tests: Python 3.13 on ubuntu-latest (push) Has been cancelled
CI / ML Framework Tests: Python 3.14 on ubuntu-latest (push) Has been cancelled
CI / Test without optional dependencies and with minimum compatible versions of dependencies (push) Has been cancelled
CI / Maximum Dependency Versions: Python 3.14 (push) Has been cancelled
CI / Type check (push) Has been cancelled
CI / Format (push) Has been cancelled
CI / Check for unused/wildcard imports (push) Has been cancelled
CI / Lint Notebooks (push) Has been cancelled
GitHub Markdown Links / test (push) Has been cancelled
GitHub Pages / links (push) Has been cancelled
292 行
15 KiB
Markdown
292 行
15 KiB
Markdown
<!-- WEHUB_ZH_README -->
|
||
> [!NOTE]
|
||
> 本文档由 WeHub 基于上游 README 翻译整理,属于社区翻译,非官方中文文档。
|
||
> [English](./README.en.md) · [原始项目](https://github.com/cleanlab/cleanlab) · [上游 README](https://github.com/cleanlab/cleanlab/blob/HEAD/README.md)
|
||
> 原作者、版权与许可证归属以原始项目及本仓库 LICENSE 文件为准。
|
||
|
||
<div align="center">
|
||
<img src="https://raw.githubusercontent.com/cleanlab/assets/master/cleanlab/cleanlab_logo_open_source.png" width=60%>
|
||
</div>
|
||
|
||
<div align="center">
|
||
<a href="https://pypi.org/pypi/cleanlab/" target="_blank"><img src="https://img.shields.io/pypi/v/cleanlab.svg" alt="pypi_versions"></a>
|
||
<a href="https://pypi.org/pypi/cleanlab/" target="_blank"><img src="https://img.shields.io/badge/python-3.10%2B-blue" alt="py_versions"></a>
|
||
<a href="https://app.codecov.io/gh/cleanlab/cleanlab" target="_blank"><img src="https://codecov.io/gh/cleanlab/cleanlab/branch/master/graph/badge.svg" alt="coverage"></a>
|
||
<a href="https://github.com/cleanlab/cleanlab/stargazers/" target="_blank"><img src="https://img.shields.io/github/stars/cleanlab/cleanlab?style=social&maxAge=2592000" alt="Github Stars"></a>
|
||
<a href="https://twitter.com/CleanlabAI" target="_blank"><img src="https://img.shields.io/twitter/follow/CleanlabAI?style=social" alt="Twitter"></a>
|
||
</div>
|
||
|
||
<h4 align="center">
|
||
<p>
|
||
<a href="https://docs.cleanlab.ai/">文档</a> |
|
||
<a href="https://github.com/cleanlab/examples">示例</a> |
|
||
<a href="https://cleanlab.ai/blog/learn/">博客</a> |
|
||
<a href="#citation-and-related-publications">研究</a>
|
||
<p>
|
||
</h4>
|
||
|
||
Cleanlab 的开源库可帮助你通过自动检测 ML 数据集中的问题来**清理**(clean)数据与**标注**(lab**el**)。为促进**在混乱的真实世界数据上进行机器学习**,这一以数据为中心的 AI(data-centric AI)包利用你*现有*的模型来估计数据集中的问题,修复这些问题后即可训练出*更优*的模型。
|
||
|
||
|
||
<p align="center">
|
||
<img src="https://raw.githubusercontent.com/cleanlab/assets/master/cleanlab/datalab_issues.png" width=74%>
|
||
</p>
|
||
<p align="center">
|
||
通过以下代码,cleanlab **自动检测**到的猫/狗(Cat/Dog)数据集中各类问题的示例:
|
||
</p>
|
||
|
||
```python
|
||
lab = cleanlab.Datalab(data=dataset, label="column_name_for_labels")
|
||
# Fit any ML model, get its feature_embeddings & pred_probs for your data
|
||
lab.find_issues(features=feature_embeddings, pred_probs=pred_probs)
|
||
lab.report()
|
||
```
|
||
|
||
- 使用 cleanlab 自动检查各类数据集:[文本](https://docs.cleanlab.ai/stable/tutorials/datalab/text.html), [音频](https://docs.cleanlab.ai/stable/tutorials/datalab/audio.html), [图像](https://docs.cleanlab.ai/stable/tutorials/datalab/image.html), 或 [表格](https://docs.cleanlab.ai/stable/tutorials/datalab/tabular.html) 数据集。
|
||
- 使用 cleanlab 自动:[检测数据问题(异常值、重复项、标注错误等)](https://docs.cleanlab.ai/stable/tutorials/datalab/datalab_quickstart.html), [训练鲁棒模型](https://docs.cleanlab.ai/stable/tutorials/indepth_overview.html), [推断多标注者数据的共识与标注者质量](https://docs.cleanlab.ai/stable/tutorials/multiannotator.html), [建议下一步应(重新)标注的数据(主动学习)](https://github.com/cleanlab/examples/blob/master/active_learning_multiannotator/active_learning.ipynb).
|
||
|
||
|
||
---
|
||
|
||
|
||
## 运行 cleanlab 开源版
|
||
|
||
此 cleanlab 包运行于 Python 3.10+,支持 Linux、macOS 以及 Windows。
|
||
|
||
- 从[这里](https://docs.cleanlab.ai/)! 开始入门。可通过 `uv`、`pip` 或 `conda` 安装。
|
||
- 从源码安装最新开发版的开发者请参阅[此 master 分支文档](https://docs.cleanlab.ai/master/index.html).
|
||
|
||
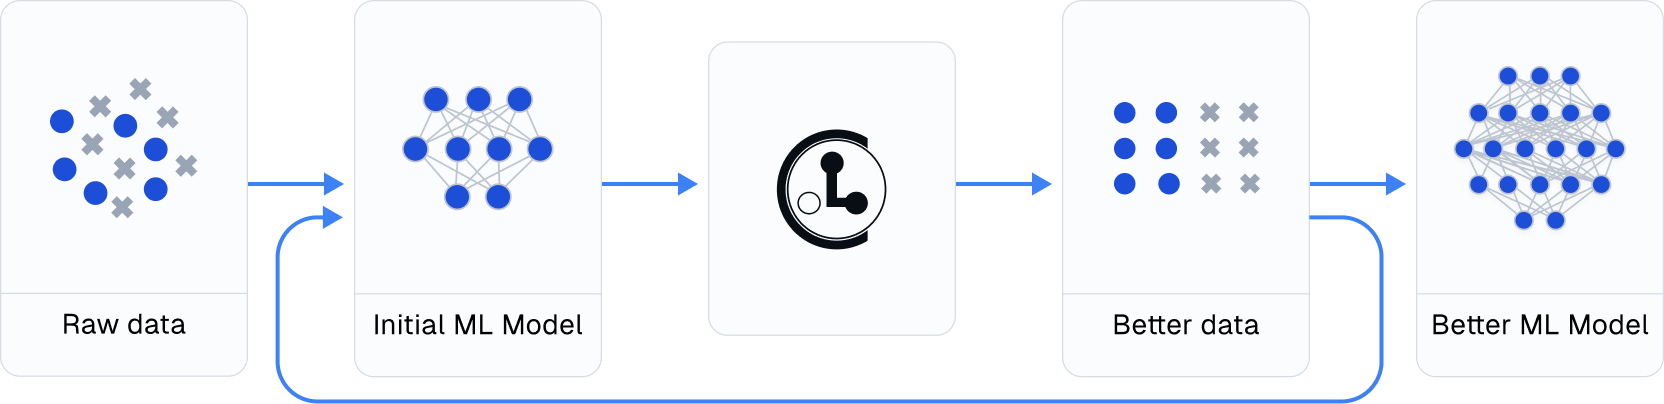
**实践以数据为中心的 AI 可以是这样:**
|
||
1. 在原始数据集上训练初始 ML 模型。
|
||
2. 利用该模型诊断数据问题(通过 cleanlab 方法)并改进数据集。
|
||
3. 在改进后的数据集上训练同一模型。
|
||
4. 尝试各种建模技术以进一步提升性能。
|
||
|
||
多数人直接从步骤 1 跳到 4,但借助 cleanlab,你无需对建模代码做任何修改也可能获得巨大提升!
|
||
通过反复执行步骤 2 → 4 持续提升性能(并尽量使用*清洗后*的数据进行评估)。
|
||
|
||
|
||
|
||
|
||
## 将 cleanlab 用于任意模型及大多数 ML 任务
|
||
|
||
cleanlab 的全部功能均可配合**任意数据集**与**任意模型**使用。是的,任意模型:PyTorch、Tensorflow、Keras、JAX、HuggingFace、OpenAI、XGBoost、scikit-learn 等。
|
||
|
||
cleanlab 适用于种类繁多的机器学习任务。此以数据为中心的 AI 包为以下特定任务提供专门功能:
|
||
1. [二分类与多分类](https://docs.cleanlab.ai/stable/tutorials/indepth_overview.html)
|
||
2. [多标签分类](https://docs.cleanlab.ai/stable/tutorials/multilabel_classification.html)(例如图像/文档标注)
|
||
3. [Token 分类](https://docs.cleanlab.ai/stable/tutorials/token_classification.html)(例如文本中的实体识别)
|
||
4. [回归](https://docs.cleanlab.ai/stable/tutorials/regression.html)(预测数据集中的数值列)
|
||
5. [图像分割](https://docs.cleanlab.ai/stable/tutorials/segmentation.html)(带逐像素标注的图像)
|
||
6. [目标检测](https://docs.cleanlab.ai/stable/tutorials/object_detection.html)(带边界框标注的图像)
|
||
7. [由多名标注者标注数据的分类](https://docs.cleanlab.ai/stable/tutorials/multiannotator.html)
|
||
8. [多名标注者的主动学习](https://github.com/cleanlab/examples/blob/master/active_learning_multiannotator/active_learning.ipynb)(建议标注或重新标注哪些数据最能提升模型)
|
||
9. [异常值检测](https://docs.cleanlab.ai/stable/tutorials/outliers.html)(识别看似分布外的非典型数据)
|
||
|
||
对于其他 ML 任务,若恰当应用,cleanlab 仍可帮助你改进数据集。
|
||
请参阅我们的[示例 Notebook](https://github.com/cleanlab/examples) 与[博客](https://cleanlab.ai/blog/learn/).
|
||
|
||
|
||
## 如此清新,如此 cleanlab
|
||
|
||
除了自动捕获潜藏在你数据中的[各类问题](https://docs.cleanlab.ai/stable/cleanlab/datalab/guide/issue_type_description.html),这一以数据为中心的 AI 包还可帮助你处理**噪声标注**,并训练更**鲁棒的 ML 模型**。
|
||
示例如下:
|
||
|
||
```python
|
||
|
||
# cleanlab works with **any classifier**. Yup, you can use PyTorch/TensorFlow/OpenAI/XGBoost/etc.
|
||
cl = cleanlab.classification.CleanLearning(sklearn.YourFavoriteClassifier())
|
||
|
||
# cleanlab finds data and label issues in **any dataset**... in ONE line of code!
|
||
label_issues = cl.find_label_issues(data, labels)
|
||
|
||
# cleanlab trains a robust version of your model that works more reliably with noisy data.
|
||
cl.fit(data, labels)
|
||
|
||
# cleanlab estimates the predictions you would have gotten if you had trained with *no* label issues.
|
||
cl.predict(test_data)
|
||
|
||
# A universal data-centric AI tool, cleanlab quantifies class-level issues and overall data quality, for any dataset.
|
||
cleanlab.dataset.health_summary(labels, confident_joint=cl.confident_joint)
|
||
```
|
||
|
||
cleanlab 通过最先进的*置信学习*(confident learning)算法来**清理**你数据的**标注**,相关算法发表于此[论文](https://jair.org/index.php/jair/article/view/12125) 与[博客](https://l7.curtisnorthcutt.com/confident-learning).。可在 [labelerrors.com](https://labelerrors.com). 查看部分经 cleanlab 清洗的数据集。
|
||
|
||
cleanlab 具备:
|
||
|
||
1. **有理论支撑**——即使模型不完美,也能对标注噪声进行精确估计,并具有[可证明的保证](https://arxiv.org/abs/1911.00068)。
|
||
2. **快速**——代码已并行化且可扩展。
|
||
4. **易于使用**——一行代码即可找出错误标注、劣质标注者、异常值,或训练抗噪声模型。
|
||
6. **通用**——适用于**[任意数据集](https://labelerrors.com/)****(文本、图像、表格、音频等)+ **任意模型**(PyTorch、OpenAI、XGBoost 等)
|
||
<br/>
|
||
|
||
|
||
<p align="center">
|
||
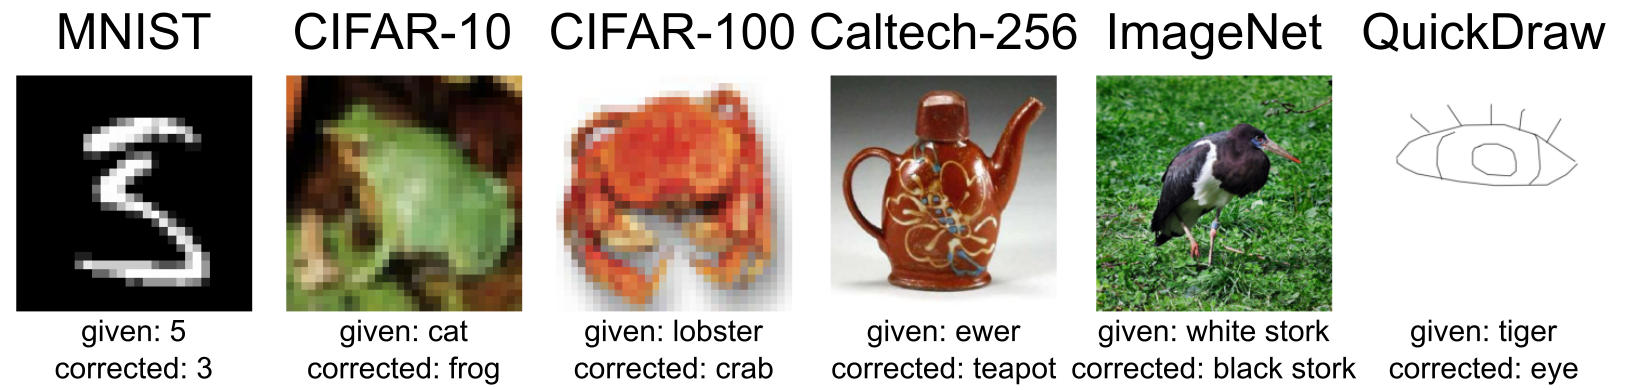
使用 cleanlab <a href="https://l7.curtisnorthcutt.com/label-errors">发现并纠正</a>的各类图像数据集中错误给定标注的示例。
|
||
尽管这些示例来自图像数据集,该方法同样适用于文本、音频、表格数据。
|
||
</p>
|
||
|
||
## 引用与相关出版物
|
||
|
||
cleanlab 基于同行评审的研究。若你使用本软件包,可引用以下相关论文:
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/1911.00068">Confident Learning (JAIR '21)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@article{northcutt2021confidentlearning,
|
||
title={Confident Learning: Estimating Uncertainty in Dataset Labels},
|
||
author={Curtis G. Northcutt and Lu Jiang and Isaac L. Chuang},
|
||
journal={Journal of Artificial Intelligence Research (JAIR)},
|
||
volume={70},
|
||
pages={1373--1411},
|
||
year={2021}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/1705.01936">Rank Pruning (UAI '17)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{northcutt2017rankpruning,
|
||
author={Northcutt, Curtis G. and Wu, Tailin and Chuang, Isaac L.},
|
||
title={Learning with Confident Examples: Rank Pruning for Robust Classification with Noisy Labels},
|
||
booktitle = {Proceedings of the Thirty-Third Conference on Uncertainty in Artificial Intelligence},
|
||
series = {UAI'17},
|
||
year = {2017},
|
||
location = {Sydney, Australia},
|
||
numpages = {10},
|
||
url = {http://auai.org/uai2017/proceedings/papers/35.pdf},
|
||
publisher = {AUAI Press},
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://jonasmueller.org/info/LabelQuality_icml.pdf"> Label Quality Scoring (ICML '22)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{kuan2022labelquality,
|
||
title={Model-agnostic label quality scoring to detect real-world label errors},
|
||
author={Kuan, Johnson and Mueller, Jonas},
|
||
booktitle={ICML DataPerf Workshop},
|
||
year={2022}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2210.03920"> Label Errors in Token Classification / Entity Recognition (NeurIPS '22)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{wang2022tokenerrors,
|
||
title={Detecting label errors in token classification data},
|
||
author={Wang, Wei-Chen and Mueller, Jonas},
|
||
booktitle={NeurIPS Workshop on Interactive Learning for Natural Language Processing (InterNLP)},
|
||
year={2022}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2211.13895"> Label Errors in Multi-Label Classification (ICLR '23)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{thyagarajan2023multilabel,
|
||
title={Identifying Incorrect Annotations in Multi-Label Classification Data},
|
||
author={Thyagarajan, Aditya and Snorrason, Elías and Northcutt, Curtis and Mueller, Jonas},
|
||
booktitle={ICLR Workshop on Trustworthy ML},
|
||
year={2023}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2309.00832"> Label Errors in Object Detection (ICML '23)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{tkachenko2023objectlab,
|
||
title={ObjectLab: Automated Diagnosis of Mislabeled Images in Object Detection Data},
|
||
author={Tkachenko, Ulyana and Thyagarajan, Aditya and Mueller, Jonas},
|
||
booktitle={ICML Workshop on Data-centric Machine Learning Research},
|
||
year={2023}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2307.05080"> Label Errors in Image Segmentation (ICML '23)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{lad2023segmentation,
|
||
title={Estimating label quality and errors in semantic segmentation data via any model},
|
||
author={Lad, Vedang and Mueller, Jonas},
|
||
booktitle={ICML Workshop on Data-centric Machine Learning Research},
|
||
year={2023}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2305.16583"> Detecting Errors in Numerical Data (DMLR '24)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{zhou2023errors,
|
||
title={Detecting Errors in a Numerical Response via any Regression Model},
|
||
author={Zhou, Hang and Mueller, Jonas and Kumar, Mayank and Wang, Jane-Ling and Lei, Jing},
|
||
booktitle={Journal of Data-centric Machine Learning Research},
|
||
year={2024}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2207.03061"> Out-of-Distribution Detection (ICML '22)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{kuan2022ood,
|
||
title={Back to the Basics: Revisiting Out-of-Distribution Detection Baselines},
|
||
author={Kuan, Johnson and Mueller, Jonas},
|
||
booktitle={ICML Workshop on Principles of Distribution Shift},
|
||
year={2022}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2210.06812"> CROWDLAB for Data with Multiple Annotators (NeurIPS '22)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{goh2022crowdlab,
|
||
title={CROWDLAB: Supervised learning to infer consensus labels and quality scores for data with multiple annotators},
|
||
author={Goh, Hui Wen and Tkachenko, Ulyana and Mueller, Jonas},
|
||
booktitle={NeurIPS Human in the Loop Learning Workshop},
|
||
year={2022}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2301.11856"> ActiveLab: Active learning with data re-labeling (ICLR '23)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{goh2023activelab,
|
||
title={ActiveLab: Active Learning with Re-Labeling by Multiple Annotators},
|
||
author={Goh, Hui Wen and Mueller, Jonas},
|
||
booktitle={ICLR Workshop on Trustworthy ML},
|
||
year={2023}
|
||
}
|
||
|
||
</details>
|
||
|
||
<details><summary><a href="https://arxiv.org/abs/2305.15696"> Detecting Dataset Drift and Non-IID Sampling (ICML '23)</a> (<b>点击显示 bibtex</b>) </summary>
|
||
|
||
@inproceedings{cummings2023drift,
|
||
title={Detecting Dataset Drift and Non-IID Sampling via k-Nearest Neighbors},
|
||
author={Cummings, Jesse and Snorrason, Elías and Mueller, Jonas},
|
||
booktitle={ICML Workshop on Data-centric Machine Learning Research},
|
||
year={2023}
|
||
}
|
||
|
||
</details>
|
||
|
||
要了解/引用上文未介绍的 cleanlab 其他功能,请查阅我们的 [Blog](https://cleanlab.ai/blog/learn).
|
||
|
||
|
||
## 其他资源
|
||
|
||
- [展示本软件包实际应用的 Example Notebooks](https://github.com/cleanlab/examples)
|
||
|
||
- [Cleanlab 博客](https://cleanlab.ai/blog/learn)
|
||
|
||
- [博客文章:Confident Learning 简介](https://l7.curtisnorthcutt.com/confident-learning)
|
||
|
||
- [NeurIPS 2021 论文:Pervasive Label Errors in Test Sets Destabilize Machine Learning Benchmarks](https://arxiv.org/abs/2103.14749)
|
||
|
||
- [数据-centric AI(Data-centric AI)简介(MIT IAP 课程)](https://dcai.csail.mit.edu/)
|
||
|
||
- [过往版本的发布说明](https://github.com/cleanlab/cleanlab/releases)
|
||
|
||
**有兴趣参与贡献?** 请参阅 [贡献指南](CONTRIBUTING.md)、[开发指南](DEVELOPMENT.md) 以及[实用贡献建议](https://github.com/cleanlab/cleanlab/wiki#ideas-for-contributing-to-cleanlab).
|
||
|
||
**有问题?** 请查看[我们的常见问题](https://docs.cleanlab.ai/stable/tutorials/faq.html) 和 [Github Issues](https://github.com/cleanlab/cleanlab/issues?q=is%3Aissue).
|