> [!NOTE]
> 本文档由 WeHub 基于上游 README 翻译整理,属于社区翻译,非官方中文文档。
> [English](./README.en.md) · [原始项目](https://github.com/supertone-inc/supertonic) · [上游 README](https://github.com/supertone-inc/supertonic/blob/HEAD/README.md)
> 原作者、版权与许可证归属以原始项目及本仓库 LICENSE 文件为准。
# Supertonic — 闪电般快速、端侧运行、高精度的 TTS
[](https://github.com/supertone-inc/supertonic)
[](https://huggingface.co/Supertone/supertonic-3)
[](https://huggingface.co/spaces/Supertone/supertonic-3)
[](https://supertonic3.github.io/)
[](https://supertonic.supertone.ai/voice-builder)
[](https://github.com/supertone-inc/supertonic-py)
[](https://supertone-inc.github.io/supertonic-py/)

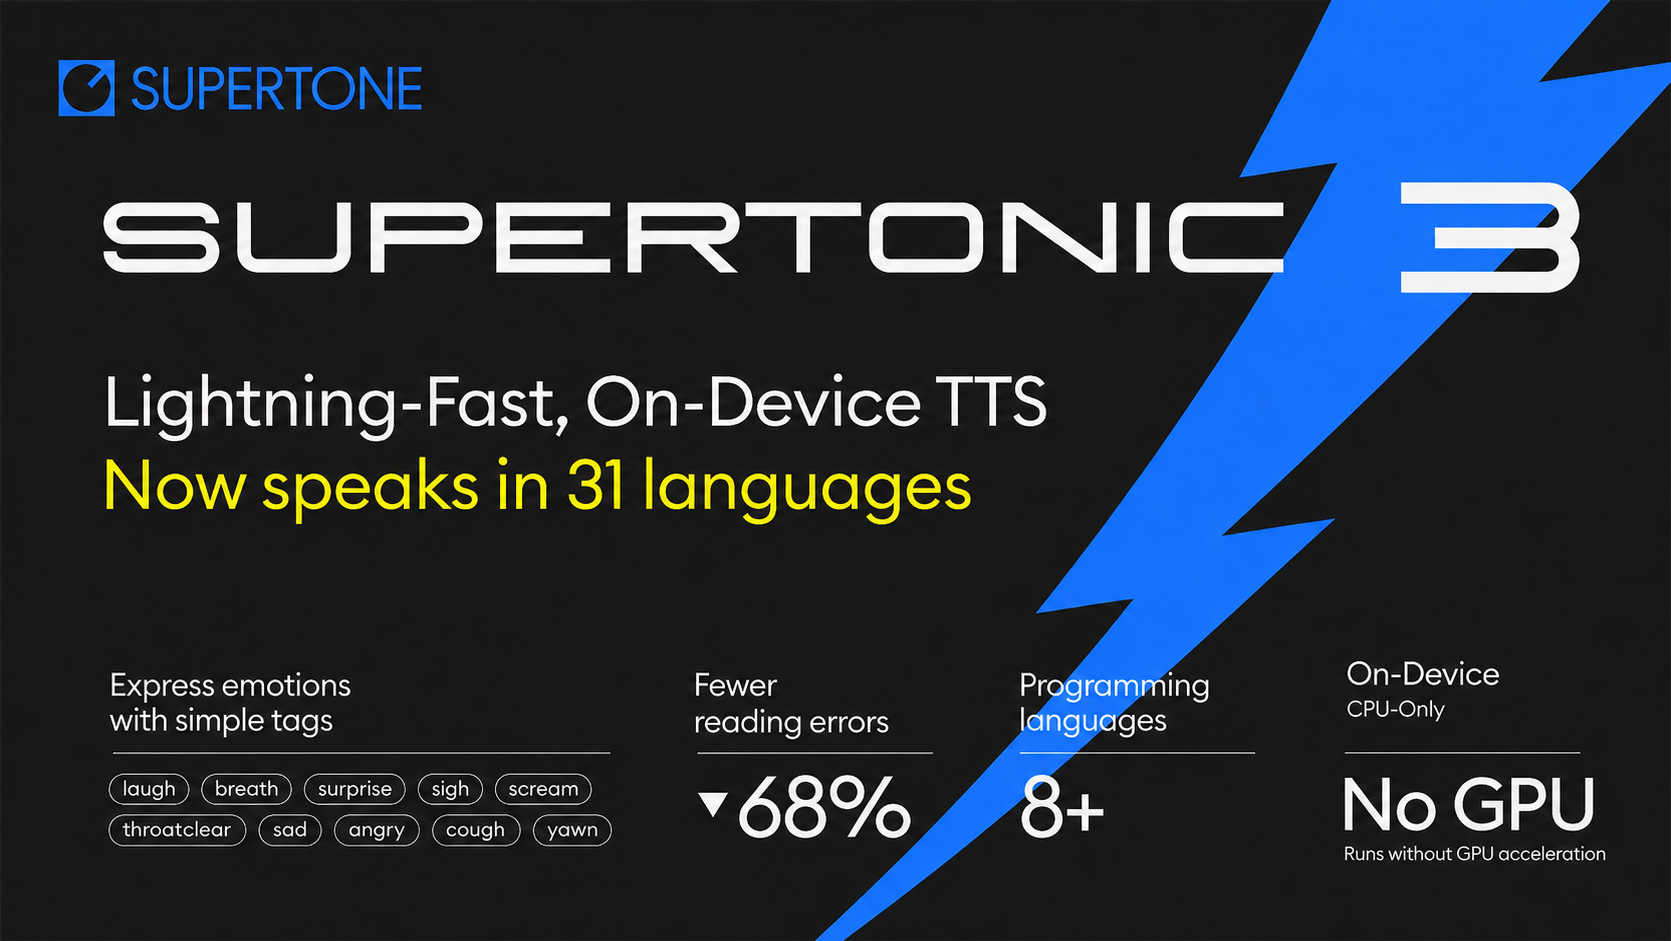
**Supertonic** 是一款闪电般快速、端侧运行的多语言文本转语音(text-to-speech,TTS)系统,专为本地推理而设计,开销极低。它由 ONNX Runtime 驱动,完全在你的设备上运行——无需云端、无需 API 调用、无需担心隐私问题。
### ✨ 亮点
- ⚡ **极速** — 低延迟、实时合成,覆盖桌面、浏览器、移动端与边缘设备——快到可在不到一秒内将整页网页转为音频
- 🌍 **31 种语言多语言支持** — 可直接从文本合成 31 种语言,或传入 `lang="na"`,在不确定输入语言时让 Supertonic 以语言无关(language-agnostic)方式处理文本——无需单独的语言适配器
- 🪶 **9900 万参数开放权重模型** — 紧凑、完全开放权重的检查点(checkpoint)——体积仅为 0.7B–2B 级开放 TTS 系统的一小部分——下载更小、冷启动更快、内存占用更低
- 📱 **边缘设备就绪** — 可在桌面、移动端、浏览器以及树莓派(Raspberry Pi)、电子阅读器等资源受限硬件上本地运行,零网络依赖、完全隐私、无需 GPU
- 🔊 **44.1kHz 高品质音频** — 直接输出录音室级 44.1kHz 16 位 WAV,可直接用于生产播放,无需任何外部升采样器(upsampler)
- 🎭 **表情标签(Expression Tags)** — 10 个内联标签(例如 ``、``、``)为生成语音带来自然的人类细微差别,无需提示工程(prompt engineering)或参考音频
- 🛠️ **多运行时 SDK** — 通过 ONNX Runtime 提供即用示例,覆盖 Python、Node.js、浏览器(WebGPU)、Java、C++、C#、Go、Swift、iOS、Rust 和 Flutter
### 🌍 支持的语言(31 种)
阿拉伯语(`ar`)、保加利亚语(`bg`)、克罗地亚语(`hr`)、捷克语(`cs`)、丹麦语(`da`)、荷兰语(`nl`)、英语(`en`)、爱沙尼亚语(`et`)、芬兰语(`fi`)、法语(`fr`)、德语(`de`)、希腊语(`el`)、印地语(`hi`)、匈牙利语(`hu`)、印尼语(`id`)、意大利语(`it`)、日语(`ja`)、韩语(`ko`)、拉脱维亚语(`lv`)、立陶宛语(`lt`)、波兰语(`pl`)、葡萄牙语(`pt`)、罗马尼亚语(`ro`)、俄语(`ru`)、斯洛伐克语(`sk`)、斯洛文尼亚语(`sl`)、西班牙语(`es`)、瑞典语(`sv`)、土耳其语(`tr`)、乌克兰语(`uk`)、越南语(`vi`)
> **不确定文本是哪种语言?** 传入 `lang="na"`,Supertonic 将以语言无关方式处理输入——无需显式语言标签。
### 📰 更新动态
- **2026.05.20** - **Supertonic 3** 现已正式支持 **[Supertone Play](https://play.supertone.ai/)** 与 **[Supertone API](https://www.supertone.ai/ko/api)**. 若你需要托管式内容创作工作流、多样预设音色与零样本(zero-shot)语音克隆,请访问 Play 或 API。
- **2026.05.18** - Python SDK v1.3.1 新增 **`supertonic serve`**,即带原生 `/v1/tts` 与 OpenAI 兼容 `/v1/audio/speech` 端点的本地 HTTP 服务器。详见 [serve 文档](https://supertone-inc.github.io/supertonic-py/cli/serve/).
- **2026.05.18** - **[Voice Builder](https://supertonic.supertone.ai/voice-builder)** 现已支持 **Supertonic 3**。为 Supertonic 创建永久自定义音色档案,并下载适用于 Supertonic 2 与 Supertonic 3 的版本专属 JSON 文件。若你已创建 Supertonic 2 音色,匹配的 Supertonic 3 JSON 现可从 [My Page](https://supertonic.supertone.ai/my-page). 获取。
- **2026.04.29** - 🎉 **Supertonic 3** 发布,支持 **31 种语言**,朗读准确度提升,重复/跳过失败更少,并提供与 v2 兼容的公开 ONNX 资源。[Demo](https://huggingface.co/spaces/Supertone/supertonic-3) | [Models](https://huggingface.co/Supertone/supertonic-3)
- **2026.01.22** - **[Voice Builder](https://supertonic.supertone.ai/voice-builder)** 正式上线!将你的声音转化为可部署、边缘原生的 TTS,并永久拥有。
- **2026.01.06** - 🎉 **Supertonic 2** 发布,支持 5 种语言。v2 代码路径保留在 [`release/supertonic-2`](https://github.com/supertone-inc/supertonic/tree/release/supertonic-2) 分支。
- **2025.12.10** - 新增 `supertonic` PyPI 包!通过 `pip install supertonic` 安装。详情见 [supertonic-py 文档](https://supertone-inc.github.io/supertonic-py)
- **2025.12.10** - 新增 [6 种新音色风格](https://huggingface.co/Supertone/supertonic/tree/b10dbaf18b316159be75b34d24f740008fddd381)(M3、M4、M5、F3、F4、F5)。详见 [Voices](https://supertone-inc.github.io/supertonic-py/voices/)
- **2025.12.08** - 通过 [OnnxSlim](https://github.com/inisis/OnnxSlim) 优化的 ONNX 模型现已在 [Hugging Face Models](https://huggingface.co/Supertone/supertonic) 提供
- **2025.11.24** - 新增 Flutter SDK 支持,兼容 macOS
---
## 快速开始
安装 Python SDK 即可立即生成语音。首次运行时,Supertonic 会自动从 Hugging Face 下载模型资源。
```bash
pip install supertonic
```
### Python
```python
from supertonic import TTS
# First run downloads the model from Hugging Face automatically.
tts = TTS(auto_download=True)
style = tts.get_voice_style(voice_name="M1")
text = "Supertonic is a lightning fast, on-device TTS system."
wav, duration = tts.synthesize(
text=text,
lang="en", # Language code (e.g., "en", "ko", "na" for language-agnostic)
voice_style=style, # Voice style object
total_steps=8, # Quality: 5 (low) to 12 (high), default 8 (medium)
speed=1.05, # Speed: 0.7 (slow) to 2.0 (fast)
)
# wav: numpy array of shape (1, num_samples,) with dtype=np.float32, sampled at 44100 Hz
# duration: numpy array of shape (1,) containing the duration of the generated audio in seconds
tts.save_audio(wav, "output.wav")
# import soundfile as sf
# sf.write("output.wav", wav.squeeze(), 44100)
print(f"Generated {duration[0]:.2f}s of audio")
```
### 本地 HTTP 服务器
Python SDK 也可将 Supertonic 作为本地 HTTP 服务运行。当你希望从已支持 HTTP 的工具调用 Supertonic 时很有用,例如本地 agent、浏览器扩展、Electron 应用、工作流自动化工具或 OpenAI 兼容的音频客户端。
```bash
pip install 'supertonic[serve]'
supertonic serve --host 127.0.0.1 --port 7788
```
启动后,可使用原生 `POST /v1/tts` 端点或 OpenAI 兼容的 `POST /v1/audio/speech` 端点。服务器还在 `http://127.0.0.1:7788/docs` 提供交互式 OpenAPI 文档。请求示例、批量合成与自定义 Voice Builder JSON 导入详见 [supertonic-py serve 指南](https://supertone-inc.github.io/supertonic-py/cli/serve/)。
## 入门
首先,克隆仓库:
```bash
git clone https://github.com/supertone-inc/supertonic.git
cd supertonic
```
### 前置条件
在运行示例之前,请下载 ONNX 模型和预设音色,并将它们放入 `assets` 目录:
> **注意:** Hugging Face 仓库使用 Git LFS。在克隆或拉取大型模型文件之前,请确保已安装并初始化 Git LFS。
> - macOS:`brew install git-lfs && git lfs install`
> - 通用:安装程序请参阅 `https://git-lfs.com`
```bash
git lfs install
git clone https://huggingface.co/Supertone/supertonic-3 assets
```
部分语言示例需要原生运行时:
- **Go**:安装 ONNX Runtime C 库。在 macOS 上,`brew install onnxruntime` 即可;Go 示例会自动检测 Homebrew 路径。
- **Java**:使用 JDK,而非仅 JRE。在 macOS 上,`brew install openjdk@17` 即可。
- **C#**:目标框架为 .NET 9,并允许主版本向前滚动(major-version roll-forward),因此 .NET 9 或更高版本的运行时均可运行。
然后运行 Python 示例:
```bash
cd py
uv sync
uv run example_onnx.py
```
这将使用默认预设音色生成 `outputs/output.wav`。
### 其他运行时示例
在其他语言和平台上运行 Supertonic
**Node.js 示例**([详情](nodejs/))
```bash
cd nodejs
npm install
npm start
```
**浏览器示例**([详情](web/))
```bash
cd web
npm install
npm run dev
```
**Java 示例**([详情](java/))
```bash
cd java
mvn clean install
mvn exec:java
```
**C++ 示例**([详情](cpp/))
```bash
cd cpp
mkdir build && cd build
cmake .. && cmake --build . --config Release
./example_onnx
```
**C# 示例**([详情](csharp/))
```bash
cd csharp
dotnet restore
dotnet run
```
**Go 示例**([详情](go/))
```bash
cd go
go mod download
go run example_onnx.go helper.go
```
**Swift 示例**([详情](swift/))
```bash
cd swift
swift build -c release
.build/release/example_onnx
```
**Rust 示例**([详情](rust/))
```bash
cd rust
cargo build --release
./target/release/example_onnx
```
**iOS 示例**([详情](ios/))
```bash
cd ios/ExampleiOSApp
xcodegen generate
open ExampleiOSApp.xcodeproj
```
在 Xcode 中:Targets → ExampleiOSApp → Signing:选择你的 Team,然后选择 iPhone 作为运行目标并构建。
---
### 技术细节
- **运行时**:ONNX Runtime,用于跨平台推理
- **浏览器支持**:onnxruntime-web,用于客户端推理
- **批处理**:支持批量推理以提升吞吐量
- **音频输出**:输出 44.1kHz 16 位 WAV 文件
## 性能亮点
Supertonic 3 面向实用的端侧推理而设计:体积足够紧凑,可在本地运行,同时仍能与体量更大的开源 TTS 系统保持竞争力。
### 朗读准确度
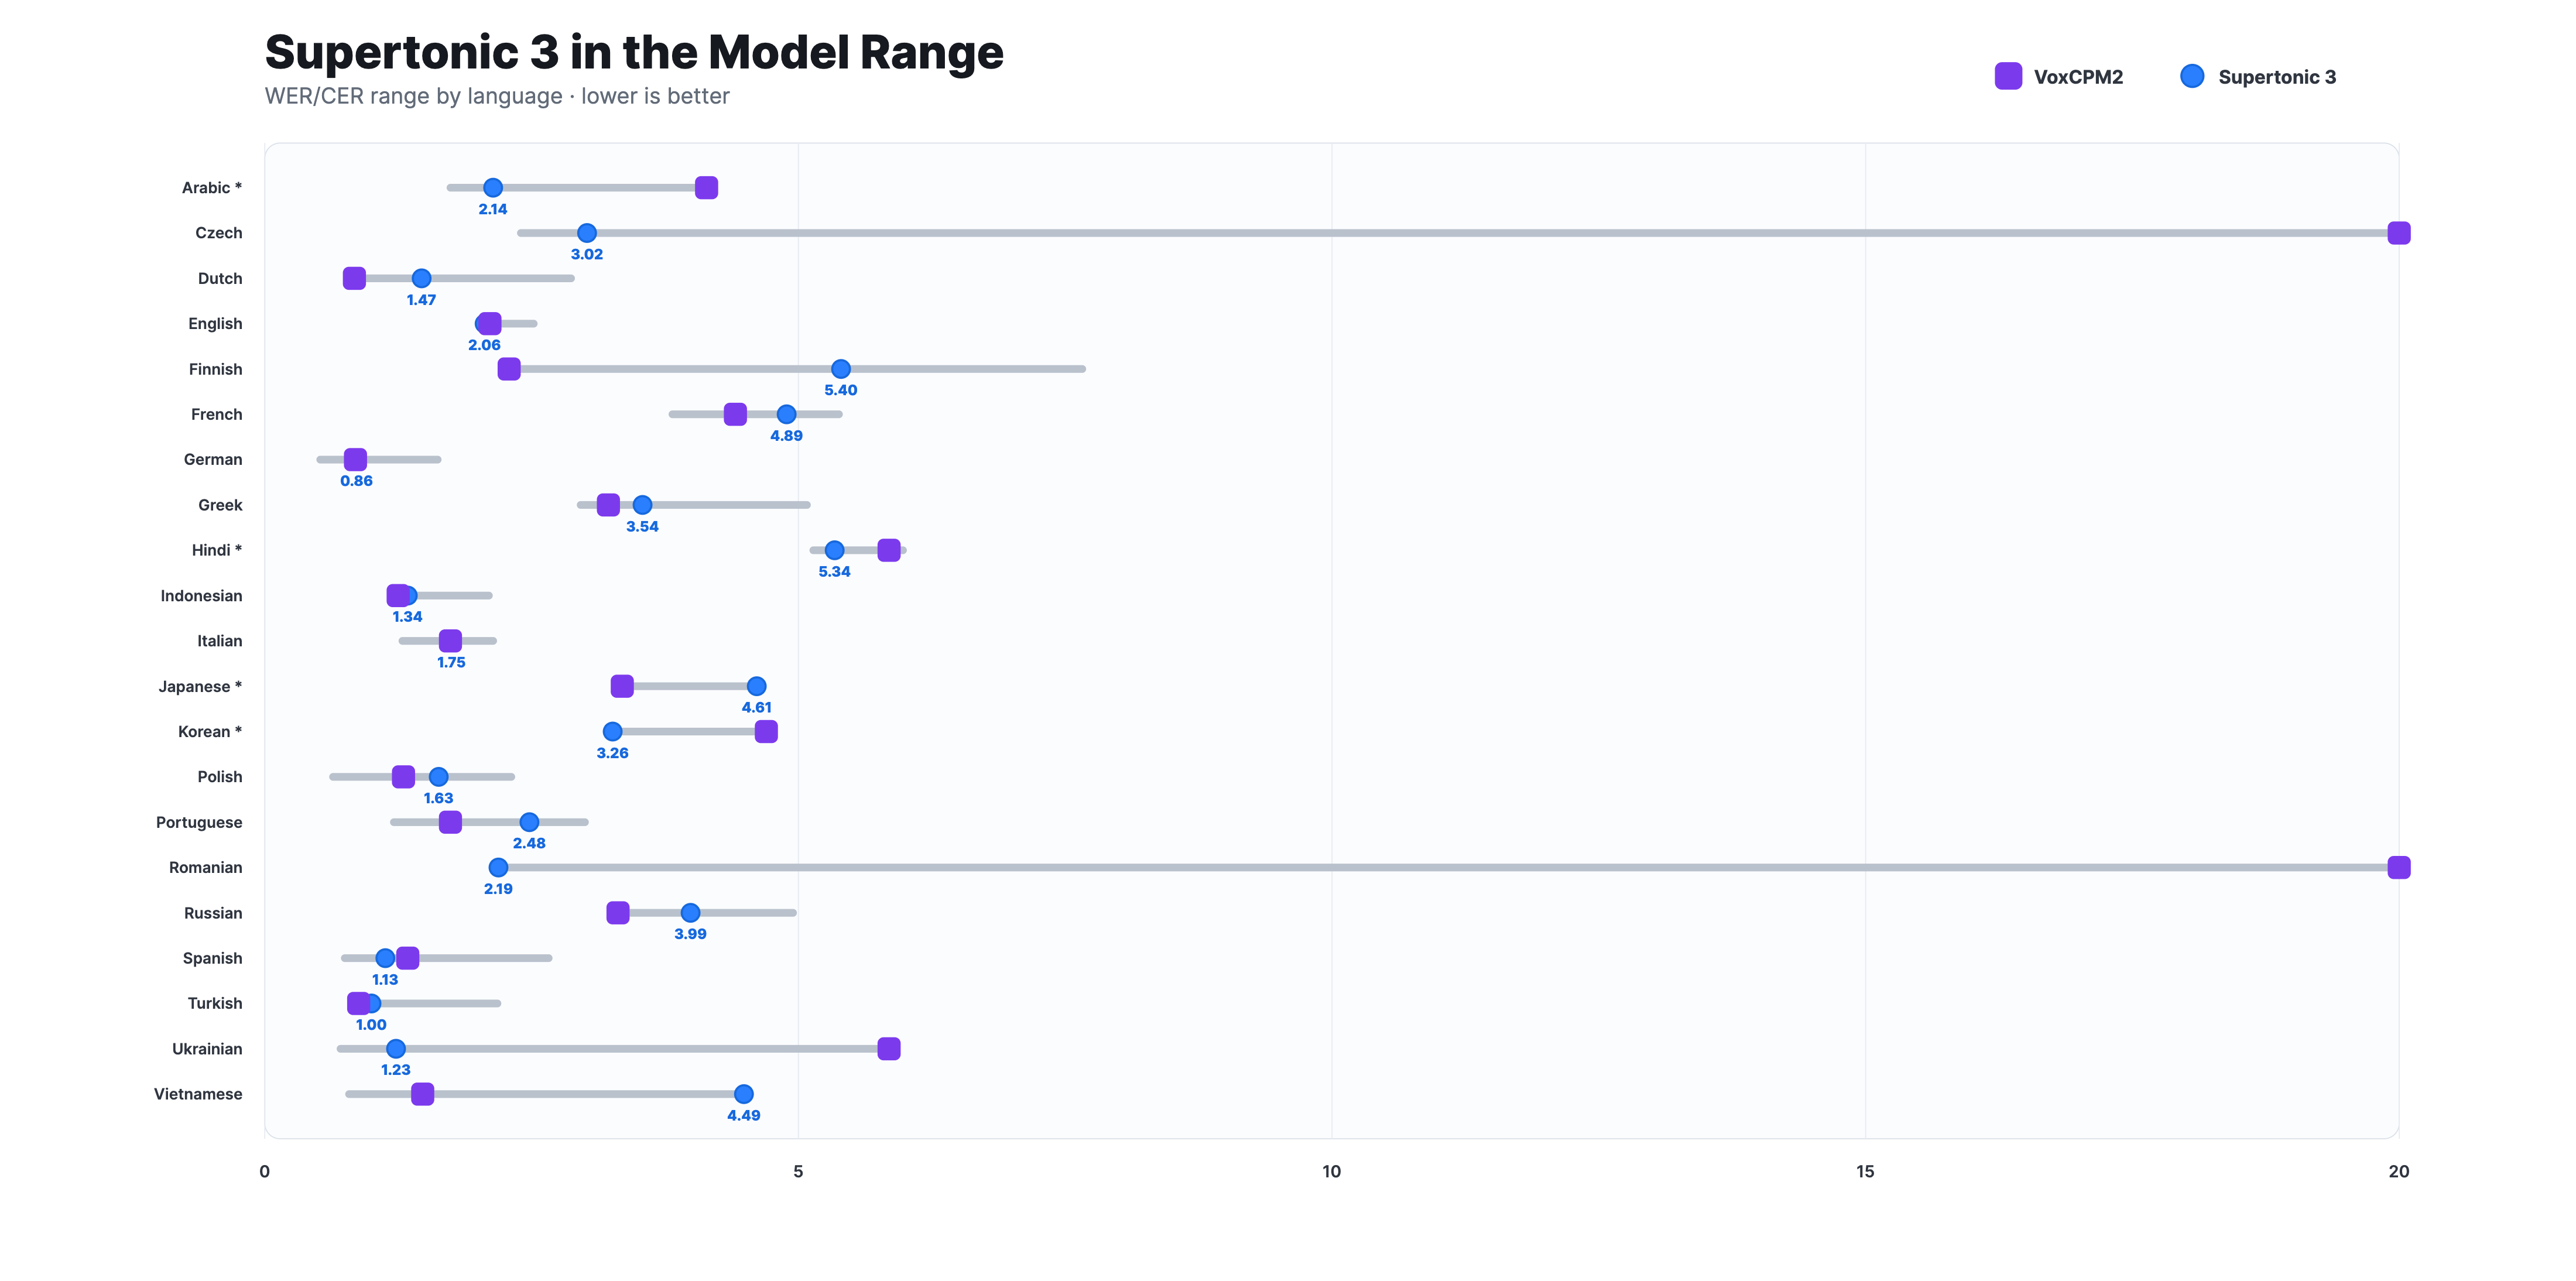
在 **[Minimax-MLS-test](https://huggingface.co/datasets/MiniMaxAI/TTS-MLS-Test) benchmark** 上评估,Supertonic 3 在 WER/CER 范围内仍具竞争力,可与 VoxCPM2 等体量更大的开源 TTS 模型相抗衡,同时保留轻量化的端侧部署路径。带星号的语言(`*`)使用 CER;其余语言使用 WER。
📊 各语言详细结果(WER / CER*)
| Lang | VoxCPM2 | OmniVoice | Qwen3-TTS | Supertonic 2 | **Supertonic 3** |
|---|:---:|:---:|:---:|:---:|:---:|
| arabic\* | 4.14 | 1.74 | — | — | **2.14** |
| czech | 23.73 | 2.40 | — | — | **3.02** |
| dutch | 0.84 | 0.77 | — | — | **1.47** |
| english | 2.11 | 2.02 | 2.25 | 2.52 | **2.06** |
| finnish | 2.29 | 3.94 | — | — | **5.40** |
| french | 4.41 | 4.74 | 3.82 | 5.09 | **4.89** |
| german | 0.85 | 0.96 | 0.52 | — | **0.86** |
| greek | 3.22 | 2.96 | — | — | **3.54** |
| hindi\* | 5.85 | 5.14 | — | — | **5.34** |
| indonesian | 1.25 | 1.67 | — | — | **1.34** |
| italian | 1.74 | 1.29 | 1.40 | — | **1.75** |
| japanese\* | 3.35 | 3.81 | 3.67 | — | **4.61** |
| korean\* | 4.70 | 3.22 | 4.07 | 3.65 | **3.26** |
| polish | 1.30 | 0.64 | — | — | **1.63** |
| portuguese | 1.74 | 1.40 | 1.21 | 1.52 | **2.48** |
| romanian | 22.39 | 2.29 | — | — | **2.19** |
| russian | 3.31 | 4.53 | 4.48 | — | **3.99** |
| spanish | 1.34 | 0.99 | 0.75 | 1.81 | **1.13** |
| turkish | 0.88 | 2.18 | — | — | **1.00** |
| ukrainian | 5.85 | 0.71 | — | — | **1.23** |
| vietnamese | 1.48 | 0.79 | — | — | **4.49** |
> 数值越低越好。`*` 表示 CER(字符错误率,character error rate);其余行使用 WER(词错误率,word error rate)。破折号(`—`)表示该模型未正式支持该语言,或暂无结果。
### Supertonic 2 到 Supertonic 3
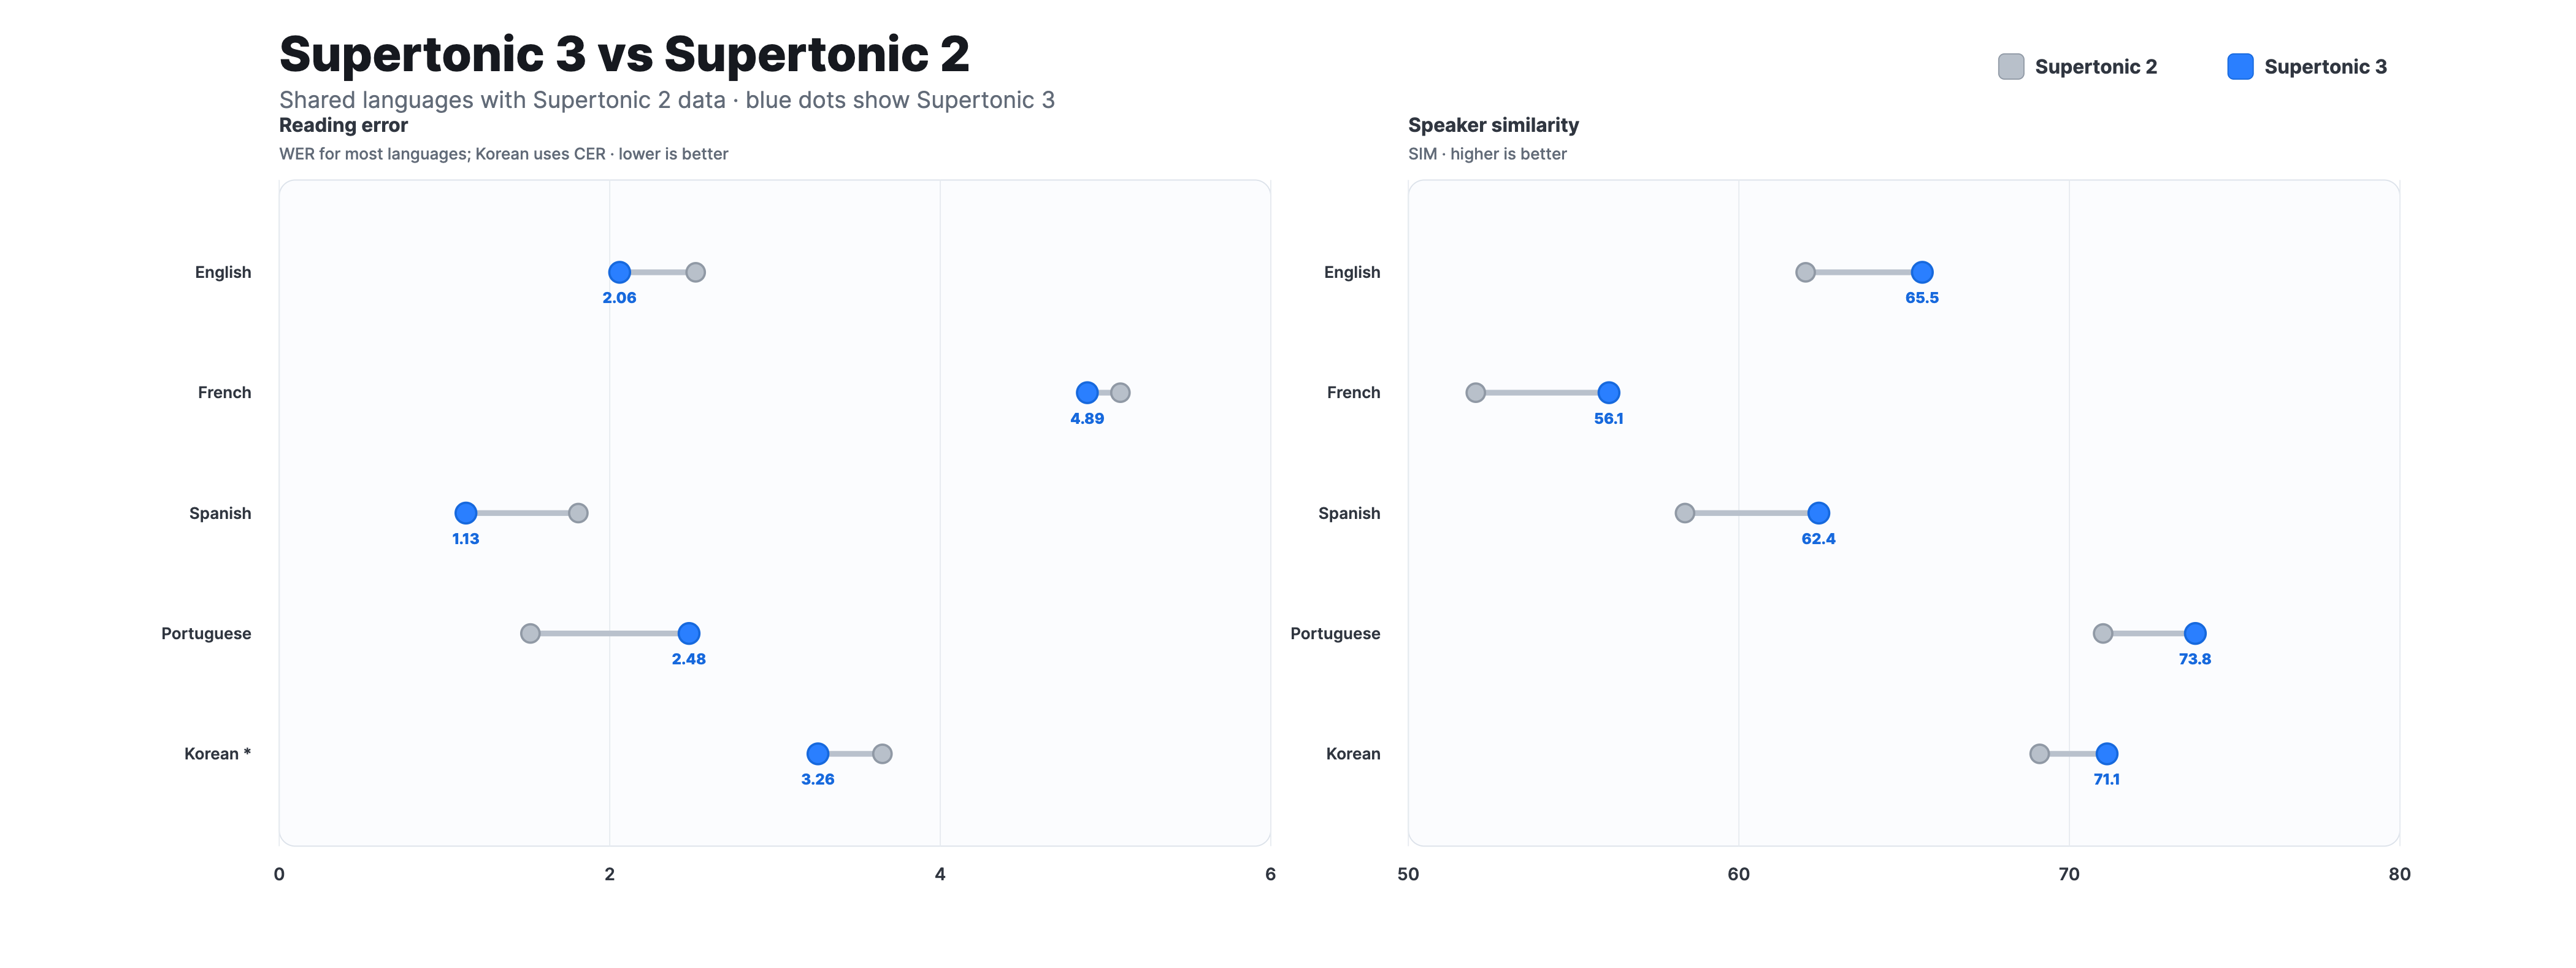
与 Supertonic 2 相比,Supertonic 3 减少了重复与跳过类失败,提升了共享语言集上的说话人相似度,并将语言覆盖从 5 种扩展到 31 种。它保持与 v2 兼容的公开 ONNX 接口,因此现有集成可在相同推理契约下迁移到 v3。
### 运行时占用
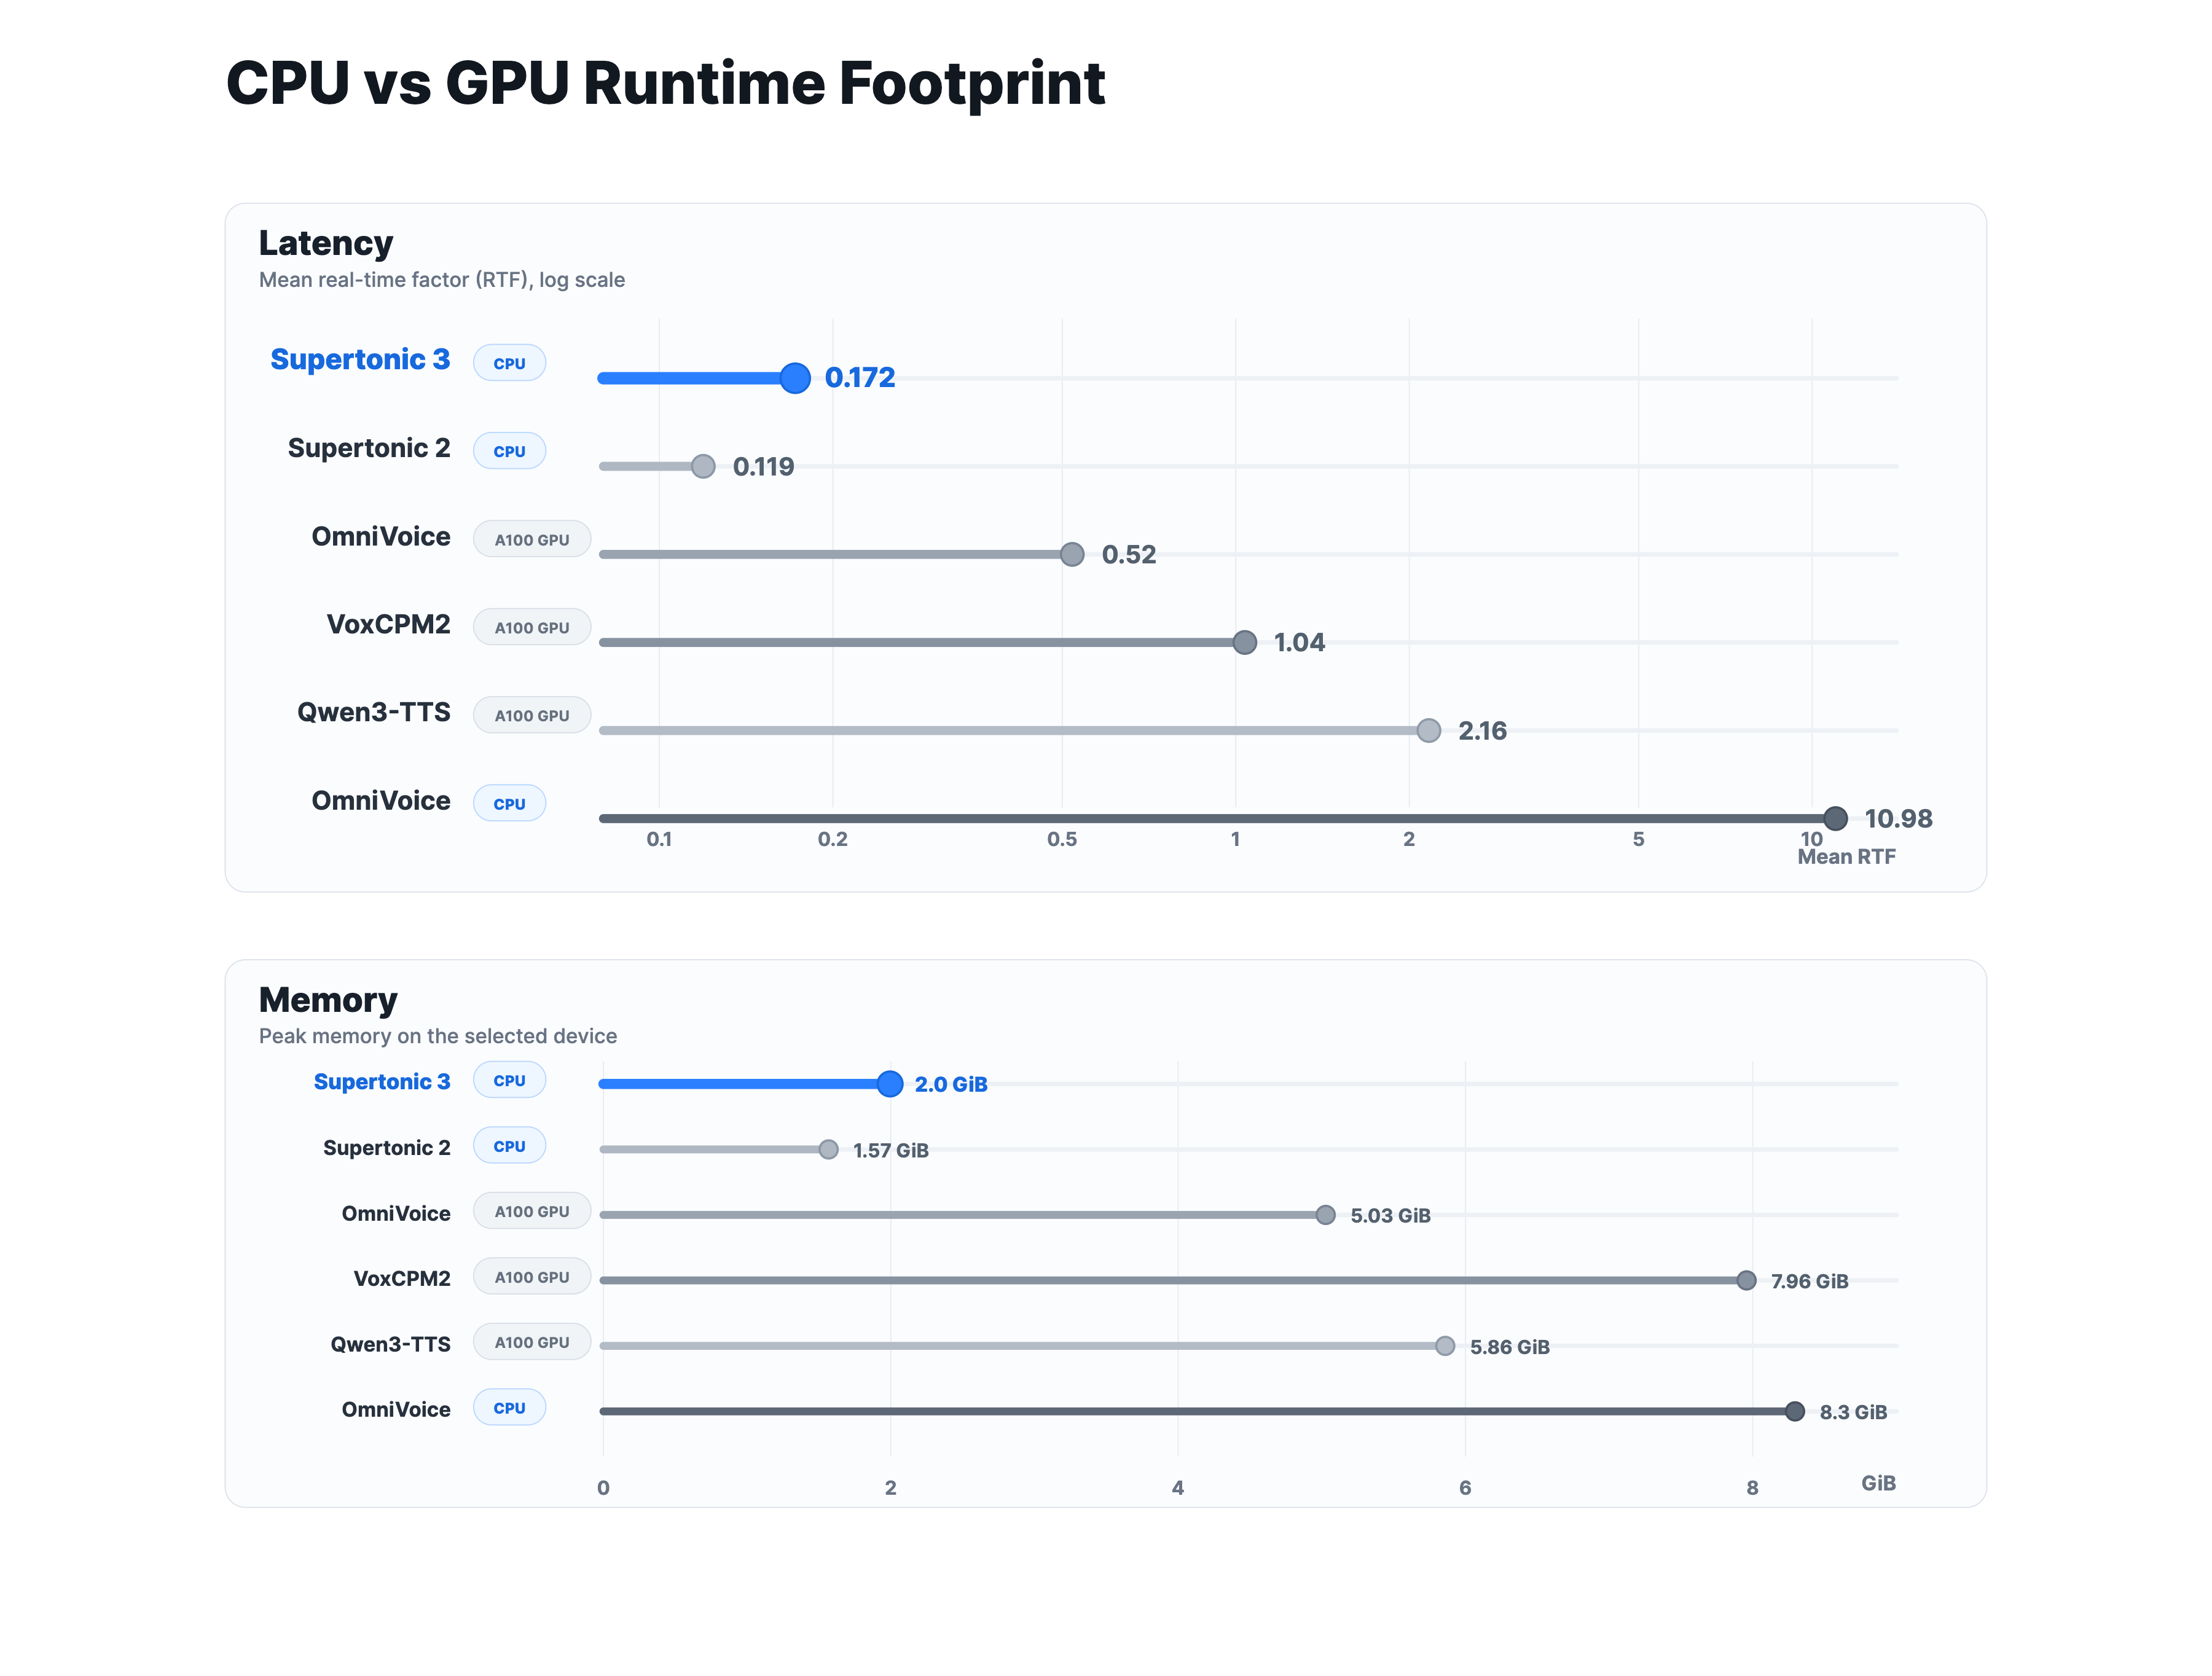
Supertonic 3 在 CPU 上运行很快,即使与在 A100 GPU 上测得的更大基线相比也如此,且内存占用显著更低。开源权重的固定音色设置无需 GPU,使本地、浏览器和边缘部署更加容易。
### 模型大小
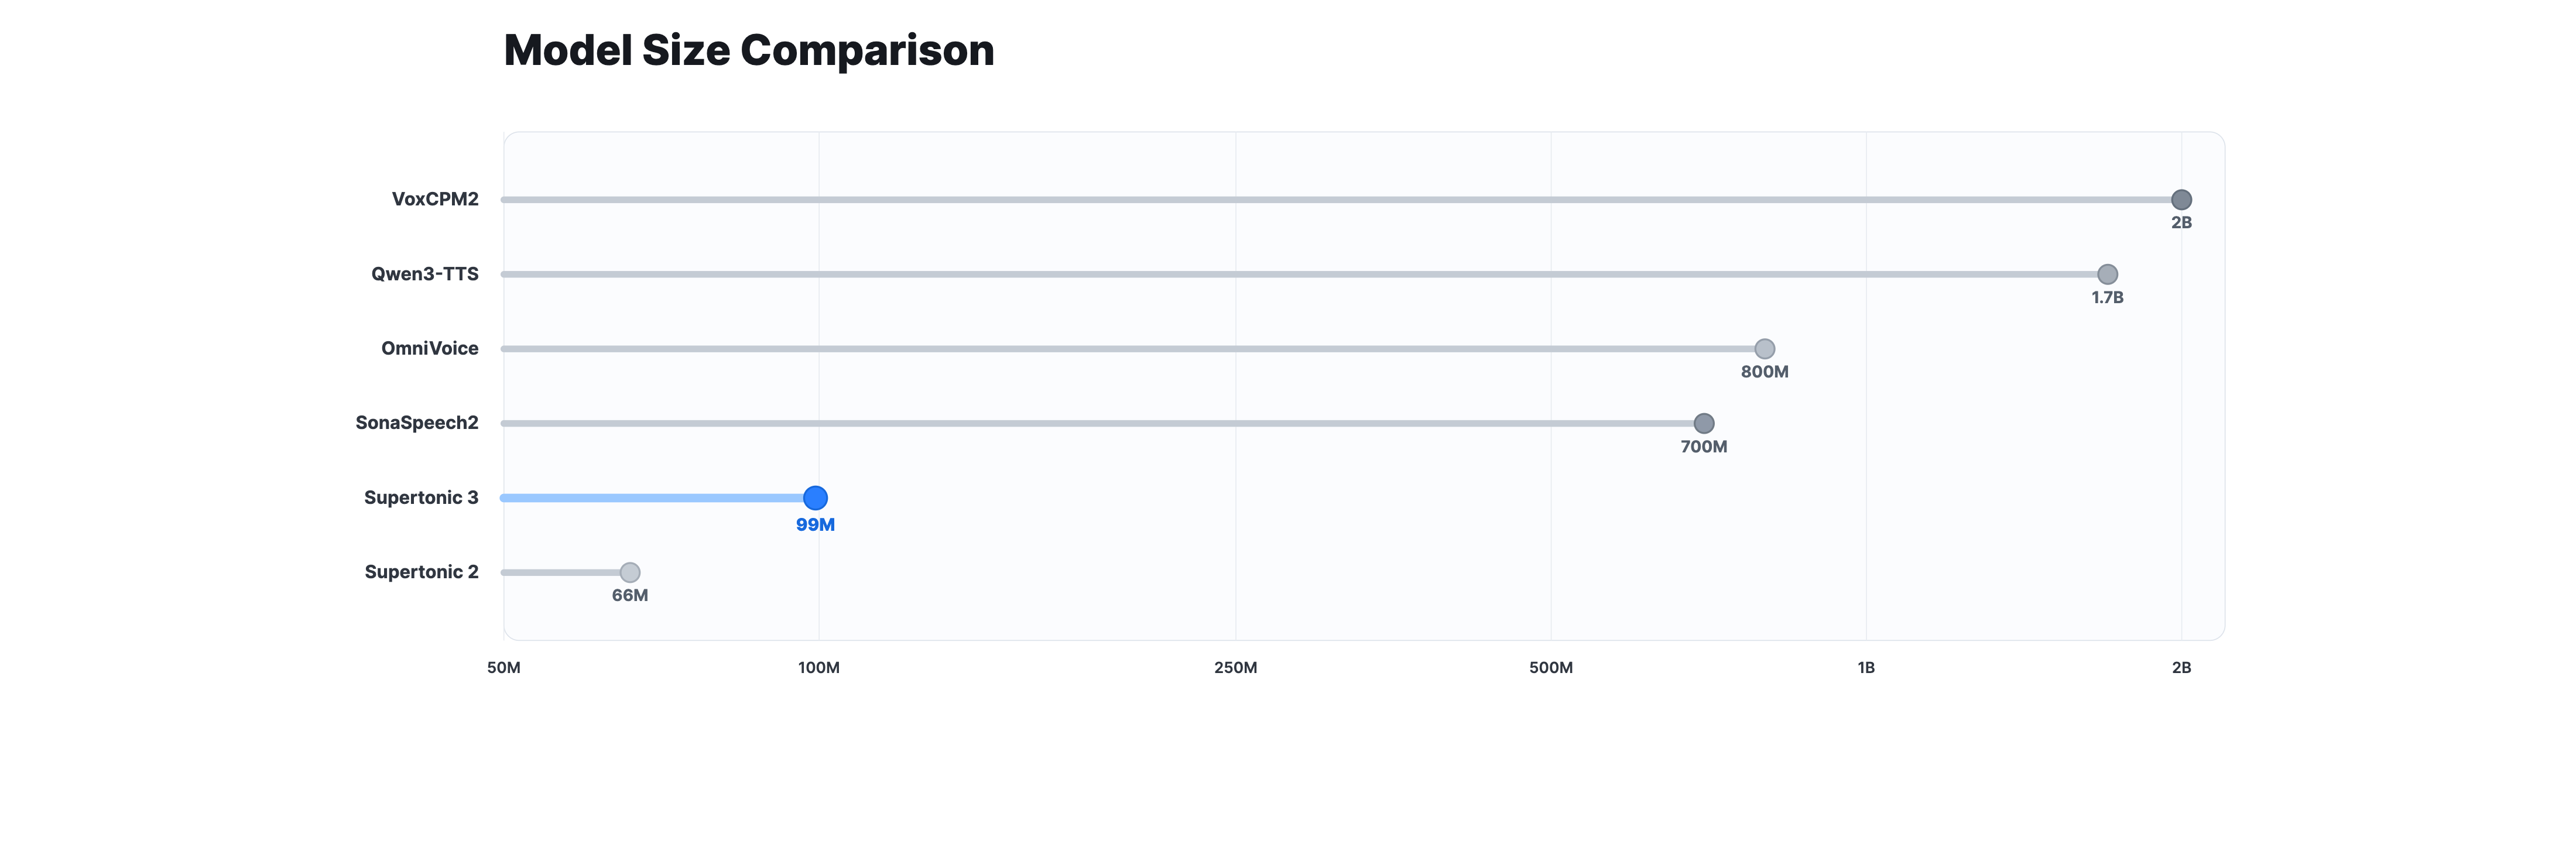
在公开 ONNX 资产中约有 99M 参数,Supertonic 3 远小于 0.7B 至 2B 级别的开源 TTS 系统。更小的模型体积在下载大小、启动时间和端侧推理方面具有实际优势。
## 声音克隆
本开源权重仓库专注于固定音色的本地 TTS,不包含官方的声音克隆流水线。若要将你自己的声音用于本地 Supertonic 部署,[Voice Builder](https://supertonic.supertone.ai/voice-builder) 可将一段简短的参考录音转换为 Supertonic 2 和 Supertonic 3 的版本特定 JSON 文件,使同一自定义音色可在支持的 Supertonic 版本间迁移。
如需托管式创作工作流,**Supertonic 3 现已在 [Supertone Play](https://play.supertone.ai/) 和 [Supertone API](https://www.supertone.ai/ko/api)**. 正式提供**。当你需要托管式内容创作工具、多样化且可商用的预设音色、零样本声音克隆(zero-shot voice cloning),或无需管理本地模型文件的 API 集成时,可使用它们。你也可以在[官方展示页](https://supertonic3.github.io/). 收听 Supertonic 3 的零样本示例。
## 演示
> **立即体验**:在浏览器中通过我们的 [**交互式演示**](https://huggingface.co/spaces/Supertone/supertonic-3), 体验 Supertonic,或从 [**Hugging Face Hub**](https://huggingface.co/Supertone/supertonic-3) 获取预训练模型开始使用。
### 树莓派
观看 Supertonic 在 **Raspberry Pi** 上运行,展示端侧、实时文本转语音合成:
https://github.com/user-attachments/assets/ea66f6d6-7bc5-4308-8a88-1ce3e07400d2
### 电子阅读器
在飞行模式下于 **Onyx Boox Go 6** 电子阅读器上体验 Supertonic,平均 RTF 为 0.3×,且完全不依赖网络:
https://github.com/user-attachments/assets/64980e58-ad91-423a-9623-78c2ffc13680
### Chrome 扩展
不到一秒即可将任意网页转为音频,提供极速、端侧文本转语音,零网络依赖——免费、私密且轻松易用:
https://github.com/user-attachments/assets/cc8a45fc-5c3e-4b2c-8439-a14c3d00d91c
## 编程语言支持
我们在多个生态中提供了开箱即用的 TTS 推理示例:
| 语言/平台 | 路径 | 说明 |
|-------------------|------|-------------|
| [**Python**](py/) | `py/` | ONNX Runtime 推理 |
| [**Node.js**](nodejs/) | `nodejs/` | 服务端 JavaScript |
| [**Browser**](web/) | `web/` | WebGPU/WASM 推理 |
| [**Java**](java/) | `java/` | 跨平台 JVM |
| [**C++**](cpp/) | `cpp/` | 高性能 C++ |
| [**C#**](csharp/) | `csharp/` | .NET 生态 |
| [**Go**](go/) | `go/` | Go 实现 |
| [**Swift**](swift/) | `swift/` | macOS 应用 |
| [**iOS**](ios/) | `ios/` | 原生 iOS 应用 |
| [**Rust**](rust/) | `rust/` | 内存安全的系统级实现 |
| [**Flutter**](flutter/) | `flutter/` | 跨平台应用 |
> 详细使用说明请参阅各语言目录下的 README.md。
## 自然文本处理
Supertonic 旨在处理包含自然散文、标点符号、缩写和专有名词的复杂真实世界文本输入。
> 🎧 **更轻松地查看音频示例**:前往我们的 [**交互式演示**](https://huggingface.co/spaces/Supertone/supertonic-3),以获得更佳的音频示例浏览体验
**测试用例概览:**
| 类别 | 主要挑战 | Supertonic | ElevenLabs | OpenAI | Gemini | Microsoft |
|:--------:|:--------------:|:----------:|:----------:|:------:|:------:|:---------:|
| 金融表达 | 带小数的货币、缩写数量级(M、K)、货币符号、货币代码 | ✅ | ❌ | ❌ | ❌ | ❌ |
| 电话号码 | 区号、连字符、分机(ext.) | ✅ | ❌ | ❌ | ❌ | ❌ |
| 技术单位 | 带单位的小数、缩写技术记号 | ✅ | ❌ | ❌ | ❌ | ❌ |
示例 1:金融表达
**文本:**
> "The startup secured **$5.2M** in venture capital, a huge leap from their initial **$450K** seed round."
**挑战:**
- 货币中的小数点($5.2M 应读作 "five point two million")
- 缩写数量级单位(M 表示 million,K 表示 thousand)
- 需要正确读作 "dollars" 的货币符号($)
**音频示例:**
| 系统 | 结果 | 音频示例 |
|--------|--------|--------------|
| **Supertonic** | ✅ | [🎧 播放音频](https://drive.google.com/file/d/1eancUOhiSXCVoTu9ddh4S-OcVQaWrPV-/view?usp=sharing) |
| ElevenLabs Flash v2.5 | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1-r2scv7XQ1crIDu6QOh3eqVl445W6ap_/view?usp=sharing) |
| OpenAI TTS-1 | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1MFDXMjfmsAVOqwPx7iveS0KUJtZvcwxB/view?usp=sharing) |
| Gemini 2.5 Flash TTS | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1dEHpNzfMUucFTJPQK0k4RcFZvPwQTt09/view?usp=sharing) |
| VibeVoice Realtime 0.5B | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1b69XWBQnSZZ0WZeR3avv7E8mSdoN6p6P/view?usp=sharing) |
示例 2:电话号码
**文本:**
> "You can reach the hotel front desk at **(212) 555-0142 ext. 402** anytime."
**挑战:**
- 括号内的区号应逐位读出
- 带连字符分隔符的电话号码(555-0142)
- 分机缩写记号(ext.)
- 分机号码(402)
**音频示例:**
| 系统 | 结果 | 音频示例 |
|--------|--------|--------------|
| **Supertonic** | ✅ | [🎧 播放音频](https://drive.google.com/file/d/1z-e5iTsihryMR8ll1-N1YXkB2CIJYJ6F/view?usp=sharing) |
| ElevenLabs Flash v2.5 | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1HAzVXFTZfZm0VEK2laSpsMTxzufcuaxA/view?usp=sharing) |
| OpenAI TTS-1 | ❌ | [🎧 播放音频](https://drive.google.com/file/d/15tjfAmb3GbjP_kmvD7zSdIWkhtAaCPOg/view?usp=sharing) |
| Gemini 2.5 Flash TTS | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1BCL8n7yligUZyso970ud7Gf5NWb1OhKD/view?usp=sharing) |
| VibeVoice Realtime 0.5B | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1c0c0YM_Qm7XxSk2uSVYLbITgEDTqaVzL/view?usp=sharing) |
示例 3:技术单位
**文本:**
> "Our drone battery lasts **2.3h** when flying at **30kph** with full camera payload."
**挑战:**
- 带缩写的小数时长(2.3h = two point three hours)
- 带缩写的速度单位(30kph = thirty kilometers per hour)
- 技术缩写(h 表示 hours,kph 表示 kilometers per hour)
- 需要正确发音的技术/工程语境
**音频示例:**
| 系统 | 结果 | 音频示例 |
|--------|--------|--------------|
| **Supertonic** | ✅ | [🎧 播放音频](https://drive.google.com/file/d/1kvOBvswFkLfmr8hGplH0V2XiMxy1shYf/view?usp=sharing) |
| ElevenLabs Flash v2.5 | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1_SzfjWJe5YEd0t3R7DztkYhHcI_av48p/view?usp=sharing) |
| OpenAI TTS-1 | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1P5BSilj5xFPTV2Xz6yW5jitKZohO9o-6/view?usp=sharing) |
| Gemini 2.5 Flash TTS | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1GU82SnWC50OvC8CZNjhxvNZFKQb7I9_Y/view?usp=sharing) |
| VibeVoice Realtime 0.5B | ❌ | [🎧 播放音频](https://drive.google.com/file/d/1lUTrxrAQy_viEK2Hlu3KLLtTCe8jvbdV/view?usp=sharing) |
> **说明:** 这些示例展示了各系统如何在**无需预处理或语音标注**的情况下,处理复杂表达的文本规范化与发音。
## 基于 Supertonic 构建
| 项目 | 说明 | 链接 |
|---------|-------------|-------|
| **TLDRL** | 免费的端侧 TTS 扩展,用于朗读任意网页 | [Chrome](https://chromewebstore.google.com/detail/tldrl-lightning-tts-power/mdbiaajonlkomihpcaffhkagodbcgbme) |
| **Read Aloud** | 开源 TTS 浏览器扩展 | [Chrome](https://chromewebstore.google.com/detail/read-aloud-a-text-to-spee/hdhinadidafjejdhmfkjgnolgimiaplp) · [Edge](https://microsoftedge.microsoft.com/addons/detail/read-aloud-a-text-to-spe/pnfonnnmfjnpfgagnklfaccicnnjcdkm) · [GitHub](https://github.com/ken107/read-aloud) |
| **PageEcho** | iOS 电子书阅读应用 | [App Store](https://apps.apple.com/us/app/pageecho/id6755965837) |
| **VoiceChat** | 浏览器中的端侧语音到语音 LLM 聊天机器人 | [Demo](https://huggingface.co/spaces/RickRossTN/ai-voice-chat) · [GitHub](https://github.com/irelate-ai/voice-chat) |
| **OmniAvatar** | 由照片 + 语音生成会说话的数字人视频 | [Demo](https://huggingface.co/spaces/alexnasa/OmniAvatar) |
| **CopiloTTS** | 基于 ONNX Runtime 的 Kotlin Multiplatform TTS SDK | [GitHub](https://github.com/sigmadeltasoftware/CopiloTTS) |
| **Aftertone** | 面向 Cursor 与 Claude Code 的本地回复后 TTS(Supertonic 3 ONNX,端侧守护进程) | [GitHub](https://github.com/omarelkhal/aftertone) · [Demo](https://github.com/omarelkhal/aftertone/releases/download/demo-asset/demo.mp4) |
| **Voice Mixer** | 用于混合与修改语音风格的 PyQt5 工具 | [GitHub](https://github.com/Topping1/Supertonic-Voice-Mixer) |
| **Supertonic MNN** | 基于 MNN 的轻量库(fp32/fp16/int8) | [GitHub](https://github.com/vra/supertonic-mnn) · [PyPI](https://pypi.org/project/supertonic-mnn/) |
| **Transformers.js** | 支持 Supertonic 的 Hugging Face JS 库 | [GitHub PR](https://github.com/huggingface/transformers.js/pull/1459) · [Demo](https://huggingface.co/spaces/webml-community/Supertonic-TTS-WebGPU) |
| **Pinokio** | 适用于 Mac、Windows 和 Linux 的一键 localhost 云环境 | [Pinokio](https://pinokio.co/) · [GitHub](https://github.com/SUP3RMASS1VE/SuperTonic-TTS) |
## 模型与版本
| | **Supertonic 3** | Supertonic 2 | Supertonic 1 |
|---|:---:|:---:|:---:|
| **状态** | 🟢 最新 | 稳定版 | 旧版 |
| **参数量** | ~99M | ~66M | ~66M |
| **语言** | 31 | 5 | 1 (en) |
| **表达标签(Expression Tags)** | ✅ 10 tags | — | — |
| **代码** | [main](https://github.com/supertone-inc/supertonic) | [release/supertonic-2](https://github.com/supertone-inc/supertonic/tree/release/supertonic-2) | — |
| **权重** | [🤗 HF](https://huggingface.co/Supertone/supertonic-3) | [🤗 HF](https://huggingface.co/Supertone/supertonic-2) | [🤗 HF](https://huggingface.co/Supertone/supertonic) |
| **交互式演示** | [🤗 Space](https://huggingface.co/spaces/Supertone/supertonic-3) | [🤗 Space](https://huggingface.co/spaces/Supertone/supertonic-2) | [🤗 Space](https://huggingface.co/spaces/Supertone/supertonic#interactive-demo) |
| **音频示例** | [DemoPage](https://supertonic3.github.io/) | — | [DemoPage](https://supertonictts.github.io/) |
## 引用
以下论文介绍了 Supertonic 中使用的核心技术。如果你在研究中使用本系统,或认为这些技术对你有帮助,请考虑引用相关论文:
### SupertonicTTS:主架构
该论文介绍了 SupertonicTTS 的整体架构,包括语音自编码器、基于流匹配(flow matching)的文本到潜变量模块,以及高效的设计选择。
```bibtex
@article{kim2025supertonic,
title={SupertonicTTS: Towards Highly Efficient and Streamlined Text-to-Speech System},
author={Kim, Hyeongju and Yang, Jinhyeok and Yu, Yechan and Ji, Seunghun and Morton, Jacob and Bous, Frederik and Byun, Joon and Lee, Juheon},
journal={arXiv preprint arXiv:2503.23108},
year={2025},
url={https://arxiv.org/abs/2503.23108}
}
```
### Length-Aware RoPE:文本-语音对齐
该论文提出了 Length-Aware Rotary Position Embedding(LARoPE),用于改进交叉注意力机制中的文本-语音对齐。
```bibtex
@article{kim2025larope,
title={Length-Aware Rotary Position Embedding for Text-Speech Alignment},
author={Kim, Hyeongju and Lee, Juheon and Yang, Jinhyeok and Morton, Jacob},
journal={arXiv preprint arXiv:2509.11084},
year={2025},
url={https://arxiv.org/abs/2509.11084}
}
```
### Self-Purifying Flow Matching:使用噪声标签训练
该论文介绍了自净化(self-purification)技术,用于在存在噪声或不可靠标签的情况下稳健地训练流匹配模型。
```bibtex
@article{kim2025spfm,
title={Training Flow Matching Models with Reliable Labels via Self-Purification},
author={Kim, Hyeongju and Yu, Yechan and Yi, June Young and Lee, Juheon},
journal={arXiv preprint arXiv:2509.19091},
year={2025},
url={https://arxiv.org/abs/2509.19091}
}
```
### RobustSpeechFlow:通过基于增广的对比流匹配学习鲁棒的文本到语音轨迹
该论文介绍了 RobustSpeechFlow 技术,通过针对数据变异性优化流匹配轨迹,提升文本到语音生成的鲁棒性与质量。
```bibtex
@misc{yang2026robustspeechflowlearningrobusttexttospeech,
title={RobustSpeechFlow: Learning Robust Text-to-Speech Trajectories via Augmentation-based Contrastive Flow Matching},
author={Jinhyeok Yang and Hyeongju Kim and Yechan Yu and Joon Byun and Frederik Bous and Juheon Lee},
year={2026},
eprint={2605.22083},
archivePrefix={arXiv},
primaryClass={cs.SD},
url={https://arxiv.org/abs/2605.22083},
}
```
## 许可证
本项目的示例代码基于 MIT License 发布。——详见 [LICENSE](https://github.com/supertone-inc/supertonic?tab=MIT-1-ov-file)。
随附模型基于 OpenRAIL-M License 发布。——详见 [LICENSE](https://huggingface.co/Supertone/supertonic-3/blob/main/LICENSE) 文件。
该模型使用 PyTorch 训练,PyTorch 基于 BSD 3-Clause License 许可,但本项目不随附再分发。——详见 [LICENSE](https://docs.pytorch.org/FBGEMM/general/License.html)。
Copyright (c) 2026 Supertone Inc.